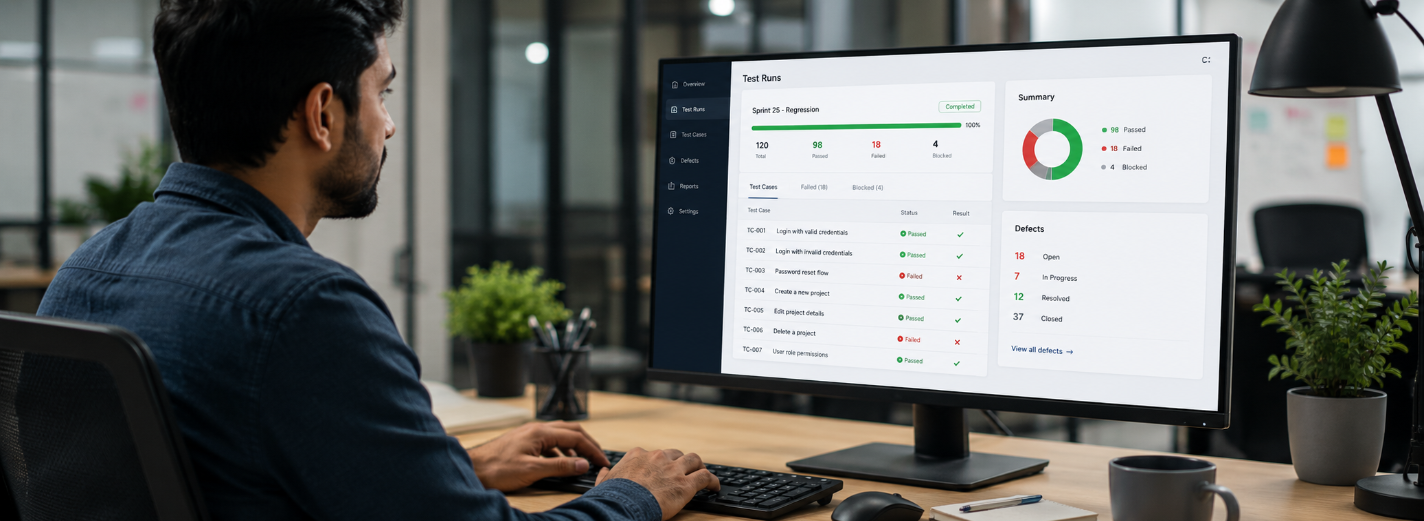
Regression Testing That Makes Every Release Safer
- QA Testing
- Regression Testing
- Test Automation
- Software Quality
Regression Testing: How to Make Every Release Safer
A release rarely fails because nobody tested anything. More often, the team tested the wrong slice of risk, learned too late, or stopped trusting a suite that cried wolf. A tiny pricing change breaks renewals; a harmless database migration changes ordering; a shared authentication update blocks one browser; a retry creates a second payment. Each defect emerges from the interaction between the change and a system whose hidden assumptions have accumulated over years.
Regression testing is the discipline of checking that behavior which worked before still works after code, configuration, data, infrastructure, or a dependency changes. Its purpose is not to repeat every historical test. It is to produce timely evidence about the business promises that may have been disturbed. A useful suite tells a team what is safe to ship, where uncertainty remains, and which failure deserves attention first.
That requires more than scripts. Strong regression testing combines change-impact analysis, tests at several levels, controlled environments and data, exploratory judgment, production feedback, and clear release policy. The result is a living safety system: quick enough to guide everyday development, deep enough to protect consequential releases, and disciplined enough that a red result still means something.
Build the Suite Around Risk, Not Feature Count
Start with impact, not a catalogue of screens. For each change, ask which customer journeys, business rules, permissions, data contracts, scheduled jobs, integrations, and operational controls it can touch. Then assess consequence and likelihood. A defect that misprices thousands of orders deserves more evidence than a cosmetic inconsistency on a rarely visited page, even if the latter is easier to automate.
Create a risk map that links product capabilities to owners, dependencies, failure modes, controls, and tests. Add evidence from incidents, support tickets, analytics, architecture changes, and code ownership. Change-impact analysis can use dependency graphs and changed files, but it needs human interpretation: a one-line feature-flag change may alter every request, while a large refactor behind a stable contract may have narrow behavior risk.
Use the map to define layers. A small commit should receive fast checks for its changed area and critical contracts. A pull request should add broader integration and selected journey coverage. A release candidate should exercise high-value flows, compatibility, migration, recovery, and operational readiness. Periodic runs can cover expensive combinations and rare scenarios. Maintain a compact always-run core for existential promises such as sign-in, authorization, order integrity, payment idempotency, and data export.
Selection is an explicit decision under uncertainty. Record why tests were included, what was excluded, and who accepted the residual risk. This makes regression scope reviewable instead of turning “we ran the suite” into a substitute for thinking.
- Business impact: revenue, safety, privacy, contractual commitments, and the number of affected users.
- Technical reach: shared services, data contracts, migrations, permissions, caches, queues, and third-party dependencies.
- Evidence strength: deterministic checks at the lowest faithful level, plus a small set of critical integrated journeys.
Put Every Check at the Right Test Level
A durable suite has many small, precise checks and relatively few broad journeys. Put a business rule in a unit or domain test when it can be proven without infrastructure. Test a service contract at the API boundary. Use integration tests for databases, queues, caches, migrations, and adapters. Reserve end-to-end tests for the thin set of risks that exists only when the assembled system and user interface work together.
This distribution improves speed and diagnosis. When a pricing rule fails in a focused test, the owning team sees the cause within seconds. When the same rule is visible only through a twenty-step browser journey, the failure may look like a login, environment, selector, timing, or data problem. Google’s testing guidance has long warned that suites dominated by end-to-end checks are slow, difficult to diagnose, and vulnerable to shared-environment failures.
Design tests around observable contracts, not implementation trivia. Assert the calculation, state transition, authorization decision, emitted event, persisted record, or user-visible outcome. Avoid tests that merely mirror private methods; they increase maintenance while adding little independent evidence. At the UI level, use semantic roles, labels, text, or explicit test identifiers instead of DOM paths and styling classes. Playwright’s official best practices recommend user-facing locators and isolated tests for the same reason: they survive harmless implementation changes and reduce cascading failures.
The right level is the lowest one that can expose the risk faithfully. Lower does not always mean better: accessibility, browser integration, and a real checkout still require the assembled experience. The goal is a portfolio in which each check earns its cost.
Use Automation and Human Judgment Together
Automation excels at repeatable comparison. It can execute the same rule across thousands of inputs, verify contracts on every commit, exercise supported browsers, and preserve evidence at three in the morning. It is poor at noticing that a workflow has become confusing, that an error message sends a customer in circles, or that a new capability creates a risk nobody encoded.
Use people where observation, interpretation, and discovery matter. Exploratory testing should begin with a charter: a risk, a customer, a change, a time box, and useful evidence to capture. A tester might explore interrupted checkout, conflicting permissions, a timezone boundary, recovery after a lost connection, or the transition between old and new versions. Pair domain experts with engineers when the correctness of tax, clinical, logistics, or financial behavior depends on context that is not obvious from requirements.
Automate a scenario when it is valuable, repeatable, stable enough to assert, and likely to repay its maintenance cost. Keep it manual when the feature is still moving quickly, the question is aesthetic or exploratory, or the setup costs more than the signal. The same scenario may evolve: explore it manually while learning, encode stable rules at lower levels, and retain a small end-to-end check for the integrated promise.
Automation is also software. Give it ownership, review, design standards, refactoring, observability, and a retirement policy. A test with no clear risk, no responsible owner, or no history of useful failures is inventory, not protection. Delete or redesign it before it makes every future change more expensive.
Turn CI/CD Into a Fast, Proportionate Quality Gate
A regression system must return its most useful answer while the developer still remembers the change. Run formatting, static analysis, focused unit tests, and affected contracts first. Parallelize independent checks and reuse immutable build artifacts. Follow with integration and selected browser tests. Move long compatibility matrices, migration rehearsals, resilience experiments, and full journeys to release or scheduled pipelines according to risk.
Make the gate proportionate. A failed deterministic test for payment integrity should block a merge. A known low-risk observability problem may create a warning and an owner. Quarantine is acceptable only as a short, visible state with a ticket, deadline, and preserved signal; silently retrying until green teaches the organization to ignore uncertainty. Limit automatic retries to gathering diagnostic evidence, and report both the first failure and the retry outcome.
GitHub’s protected-branch controls can require status checks before a merge. The technical switch is easy; choosing trustworthy checks is the real governance work. Give jobs unique names, publish ownership and expected duration, and provide logs, traces, screenshots, diffs, and the relevant seed or request ID when they fail.
Do not make one enormous pipeline the only path to confidence. Use change-based selection for speed, but continuously test the selector itself: run broader suites on the main branch or a sample of changes and compare missed failures. Keep an emergency path for urgent fixes, with explicit authorization, narrow scope, production monitoring, and retrospective completion of skipped evidence.
Treat the Environment and Test Data as Product Assets
Many apparent product regressions are really evidence failures. A shared account is locked, yesterday’s order remains in the database, a clock crosses midnight, a queue contains unfinished work, or a third party changes its sandbox. If tests cannot control their starting conditions, the suite measures environmental noise along with software behavior.
Provision environments from versioned configuration and record the application build, infrastructure revision, feature flags, schema, browser, service stubs, and dependency versions used for each run. Prefer isolated, disposable resources where practical. When a shared environment is unavoidable, allocate namespaces, accounts, and data by worker; make setup idempotent; and clean up through reliable APIs. Detect drift instead of letting teams debug it repeatedly.
Design test data as deliberately as production code. Use factories and scenario builders that express intent—an overdue invoice, a user with two roles, an order at a tax boundary—rather than opaque fixtures copied from production. Generate unique identifiers, fix or inject time, and preserve the random seed for a failure. Test important boundaries and distributions, including Unicode, empty values, large payloads, rounding, daylight-saving transitions, and partially migrated records.
Protect privacy. Synthetic data is the default. If production-derived data is necessary, minimize, mask, tokenize, control access, define retention, and verify that re-identification is not possible through combinations of fields. Keep destructive tests away from shared services. A credible regression result includes provenance: the exact data recipe and environment state required to reproduce it.
Turn Every Escaped Defect Into Lasting Knowledge
A production defect is expensive tuition. The waste becomes worse if the organization pays twice. Begin with a blameless reconstruction: what promise failed, who was affected, which change and conditions activated it, why existing controls did not reveal it, and what reduced the impact. Distinguish the defect from the detection gap and from the release or recovery gap; each may need a different remedy.
Add the narrowest deterministic test that would have detected the underlying behavior before release. Put it at the lowest faithful level, then add a broader check only when the failure depended on integration. Do not freeze an accidental symptom. If duplicated charges resulted from missing idempotency, test the invariant that one business request creates one charge under retry, timeout, and concurrent delivery—not the exact error text seen during the incident.
Improve the system around the test. A contract failure may call for schema validation and consumer tests. A migration defect may require backward-compatibility checks, expand-and-contract rollout, and rehearsal on representative volume. A configuration escape may require typed validation and canary comparison. A confusing operational response may demand better telemetry, runbooks, ownership, or rollback automation.
Link the incident, corrective test, code change, and monitoring signal so future maintainers understand the reason. Review recurring patterns quarterly: permission boundaries, time, retries, stale caches, partial failure, and data migrations often repeat under different names. The strongest suite is a memory of risks the organization has learned to recognize, rather than a museum of old user-interface steps.
A regression suite earns trust when a failure is rare enough to command attention, specific enough to diagnose, and early enough to change the release decision.— GARNO.TECH QA Team
Measure Confidence, Speed, and Signal Quality
Counting test cases is easy and rarely useful. Ten thousand checks may provide less confidence than two hundred well-chosen ones if they repeat the same assertions, miss important boundaries, or fail unpredictably. Measure the system by the decisions it improves.
Track feedback time by layer: time to the first meaningful failure, median and slow-tail pipeline duration, queue time, and time from a red build to diagnosis. Track signal quality: flaky-failure rate, rerun pass rate, failures caused by environment or data, and the proportion of failures with enough evidence to reproduce locally. Track maintenance: tests added, changed, quarantined, and removed; age and owner of every quarantine; slowest checks; and recurring failure clusters.
Connect testing to outcomes carefully. Monitor escaped defects by severity, customer journey, cause, and detection gap; rollback and hotfix frequency; change failure rate; incident recovery time; and support contacts after releases. Coverage can help locate untested code, but line coverage is not proof of useful assertions or meaningful scenarios. Mutation testing, contract coverage, and mapped risk coverage can reveal deeper gaps, yet none should become a target people can game.
Use a balanced review. Ask whether critical risks have evidence, whether developers receive it soon enough to act, whether the evidence can be trusted, and whether maintaining it is economically sensible. Publish trends with context and owners. The objective is not a perfect dashboard; it is a shorter path from change to justified confidence and a faster path from failure to understanding.
Regression Testing Is a Learning System
High-quality regression testing is a learning loop, not a wall built once. Product risk changes with customers, architecture, regulation, data volume, dependencies, and delivery speed. The suite must change with it. Review critical journeys and ownership when the product changes; review selection rules when architecture changes; review environments when infrastructure changes; and review release gates when the cost of delay or failure changes.
A mature team can explain the evidence behind a release. It knows which risks were tested at which level, which configurations and data were used, what failed, what remained outside scope, and who accepted that uncertainty. It gets fast local and pull-request feedback without mistaking speed for completeness. It protects the handful of business promises that cannot be compromised and applies deeper checks where consequence justifies cost.
Begin with one release stream. Map the most costly promises and recent escapes, remove or repair the noisiest tests, create a fast deterministic core, and give each gate an owner. Then add change-impact selection, reproducible data, layered coverage, and production feedback in small steps. The first sign of improvement is often not more tests; it is that a failure reaches the right person sooner and can be reproduced on the first attempt.
QA automation and regression-testing services should leave a team with more than a passing report. They should leave a maintainable test architecture, explicit risk decisions, observable pipelines, and the ability to evolve the safety system after the engagement ends. That is how testing protects delivery without becoming its bottleneck.
A Four-Stage Regression Loop for Every Meaningful Change
- /01Map change impactConnect the diff to customer journeys, business rules, contracts, dependencies, data, permissions, incidents, and owners. Rank the affected risks by consequence and likelihood, then record the residual uncertainty.
- /02Prepare deterministic evidenceSelect the lowest faithful test levels, provision known versions and isolated resources, create purpose-built data, control time and randomness, and define expected outcomes before execution.
- /03Run layered checks and investigate onceReturn focused feedback first, then broaden by risk. On failure, preserve the build, data recipe, seed, logs, traces, screenshots, and request IDs so the owner can reproduce the first result instead of rerunning blindly.
- /04Release, observe, and feed learning backDeploy progressively, watch business and technical signals, and keep rollback available. Convert escaped defects and false alarms into better tests, selection rules, data, telemetry, and ownership.
Should every regression test run for every change?
Should every regression test run for every change?
How should a team handle flaky tests?
How should a team handle flaky tests?
Which regression tests should be automated first?
Which regression tests should be automated first?
Can regression testing guarantee a bug-free release?
Can regression testing guarantee a bug-free release?
What makes a regression test a useful release gate?
What makes a regression test a useful release gate?
Need a regression system your team can trust?
Share one release flow, its critical business promises, recent escaped defects, pipeline timings, and noisy tests. We will map the risk, design a fast evidence strategy, and leave your team with a maintainable path to safer releases.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
DevOps in Digital Transformation: Build a System That Can Keep Changing
Connect product, engineering, platform, security, finance, and operations through small changes, executable infrastructure, fast feedback, safe recovery, and shared ownership.
8 min read
01 Aug 2026
React Native vs Flutter: Choose for the Product, Team, and Lifecycle
Compare React Native and Flutter through architecture, native integrations, performance, interface behavior, accessibility, ecosystem risk, team capacity, releases, and long-term ownership.
10 min read
30 Jul 2026
Azure Cloud Implementation: Migration Checklist and Mistakes
A practical Azure migration checklist for workload discovery, landing zones, strategy, identity, data, migration waves, recovery, performance, cost and operating ownership.
8 min read
04 Aug 2026