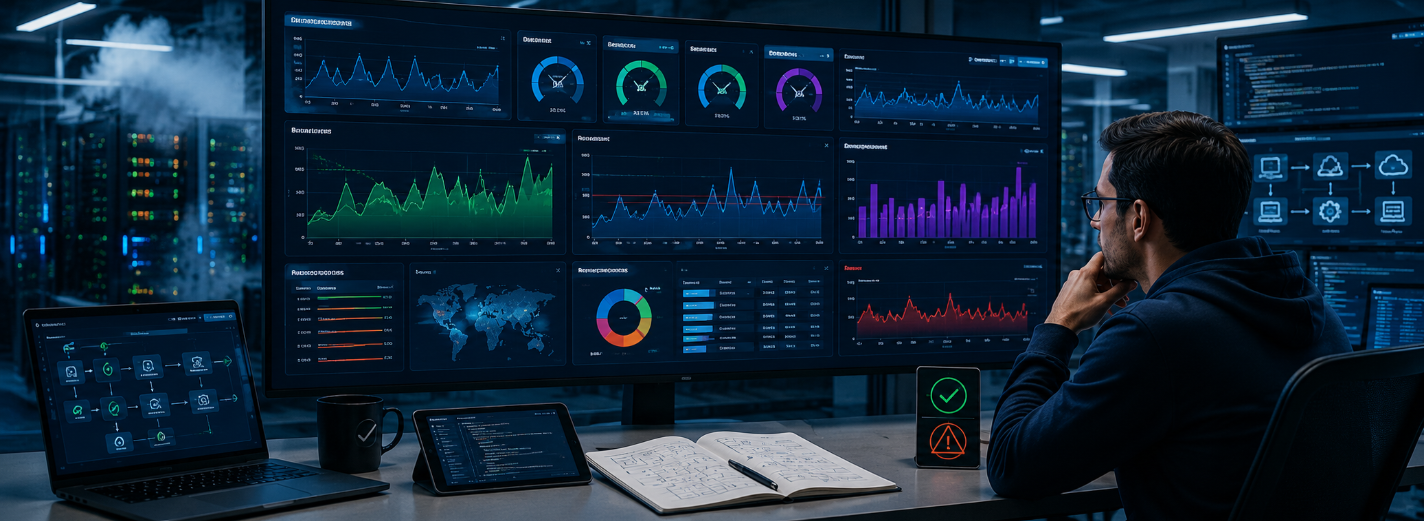
Load Testing and QA Automation: Building Confidence Before Traffic Grows
- load testing
- QA automation
- performance testing
- regression testing
- software quality
- scalable applications
Load Testing and QA Automation: How to Build Evidence for Scale
An application can pass every functional check and still fail on the day it matters most. A campaign succeeds, a batch job overlaps with the morning peak, or one slow provider causes requests to accumulate until connection pools and queues are exhausted. The visible symptom may be a timeout, but the cause often began several services away and several minutes earlier.
Load testing services are valuable when they replace hopeful capacity claims with evidence. A useful test answers specific questions: Can customers complete the important journey at the expected peak? Where does latency begin to rise? How does the system reject excess work? Does it recover without corrupting data? How much headroom remains for traffic growth or a dependency slowdown?
QA automation solves a related problem. It shortens the distance between a code change and trustworthy feedback about business risk. Together, performance testing and regression automation create a repeatable way to learn whether a release is correct, fast enough, and operationally safe. Neither discipline is a final ceremony before launch. Both belong throughout product development, tied to production telemetry and the decisions a team must make.
Measure User Outcomes, Not Just Requests per Second
Requests per second describes traffic, not success. Start with the business journey: a shopper finds a product, adds it to a cart, pays, receives confirmation, and leaves one valid order. Measure the completion rate and end-to-end duration of that journey alongside component latency. A fast HTTP 200 that returns stale data or creates a duplicate payment is a failed outcome.
Define service-level indicators from the user’s point of view and set thresholds before the test. Track p50 for the typical case and p95 or p99 for the slow tail, because averages hide the people waiting longest. Google’s SRE guidance recommends user-centered SLOs and percentiles precisely for this reason. Pair latency with error rate, throughput, saturation, and correctness. For asynchronous work, measure queue age and time to a durable result rather than the speed of the enqueue request.
The workload model must describe concurrency, arrival rate, request mix, payload sizes, data distribution, session behavior, cache state, geographic origin, background jobs, and third-party calls. Include ordinary traffic, expected peaks, sudden spikes, and sustained load. One giant test cannot answer every question: a baseline test supports comparisons, a stress test reveals the first limit, a spike test examines rapid change, and a soak test exposes leaks or gradual queue growth.
- Business completion rate, data correctness, and end-to-end journey duration—not merely HTTP status.
- p50, p95, and p99 latency by operation, paired with throughput and error rate over time.
- Saturation across pools, queues, databases, caches, CPU, memory, storage, network, and dependencies.
- Degradation, back-pressure, recovery time, and integrity after spikes, sustained load, and dependency failure.
A Credible Load Test Is an Experiment, Not a Tool Run
A test script is only the instrument. The experiment begins with a hypothesis: “At 300 checkout starts per minute, 99% should finish within four seconds, fewer than 0.5% should fail, no duplicate order should exist, and queue age should return below 30 seconds within five minutes after the peak.” That statement tells the team what to generate, observe, and accept.
Prepare conditions that make the result interpretable. The environment should preserve relevant production topology, autoscaling rules, data volume and distribution, indexes, connection limits, caches, and runtime configuration. If staging is smaller, document the difference and test a question that remains valid at that scale. Use varied accounts and inputs; repeatedly reading one cached record can produce an impressive but meaningless chart. Stub a third party when you lack permission to load it, then separately model its latency and failure behavior.
Control the load generator too. Confirm it has enough CPU, network, and file descriptors, synchronize clocks, and place generators where network distance matches the scenario. Run a low-load smoke test first to validate scripts and data. Record application version, infrastructure version, configuration, dataset, generator location, scenario, and timestamps. Reproducibility matters because optimization is a comparison: if several variables change between runs, a faster result does not explain why.
During execution, correlate what the client experiences with what every layer is doing. OpenTelemetry describes observability through traces, metrics, and logs; in a load test, their shared context turns a latency graph into a diagnosis. A rising p99 may coincide with a database connection pool at its limit, lock waits, garbage-collection pauses, a growing queue, cache eviction, thread starvation, storage throttling, or retries against a slow dependency.
Increase load in controlled steps and hold each level long enough for autoscaling, caches, queues, and background work to settle. The first saturated resource is not always the root constraint: a full worker pool may be the downstream consequence of slow queries. Watch for coordinated omission, where a generator waits on slow responses and therefore sends fewer requests exactly when the system is weakest. Verify business invariants after the run, including duplicates, missing events, incorrect balances, and unfinished jobs.
Then reduce load and measure recovery. A service that handles 1,000 requests per second but needs an hour to drain its queue has a different capacity limit than its throughput chart suggests. Repeat the same test after one controlled change and compare distributions, errors, resources, and recovery—not only the average. The final report should state the tested configuration, confidence and limitations, first bottleneck, safe operating envelope, remaining headroom, and prioritized remediation with expected impact.
Automate the Risks That Matter Most
QA automation creates value by protecting decisions that would be expensive to verify manually on every change. Start with business impact and change frequency: authentication, authorization, payments, calculations, data transformations, public contracts, and the journeys that generate revenue or fulfill a legal obligation. Automate stable behavior with clear expected results; keep exploratory testing for ambiguity, new interactions, and risks that require human judgment.
Use the cheapest test level that can detect the defect with sufficient confidence. Unit tests provide fast feedback on rules and edge cases. Component and API tests verify contracts, persistence, permissions, and failure handling without a browser. A smaller set of end-to-end tests proves that critical parts work together. Browser tests are valuable, but they are slower and more sensitive to environment, timing, and UI change; treating them as the entire strategy produces long pipelines and difficult failures.
Design tests for diagnosis. Each failure should identify the violated behavior, relevant input, expected result, and useful system evidence. Control time, randomness, and external dependencies. Create test data through supported interfaces and isolate parallel runs. A test that passes only after a retry is reporting uncertainty, not health. Track flaky tests as defects with owners and deadlines, because a suite that engineers do not trust cannot protect a release.
A maintainable automation system has an explicit purpose, architecture, and operating model. Separate test intent from technical mechanics so authentication, API clients, fixtures, and environment configuration can change without rewriting every scenario. Keep tests in version control beside the product, review them with the same care as production code, and make ownership visible by domain.
Shared mutable data, execution-order dependencies, arbitrary sleeps, unstable selectors, and uncontrolled providers are common sources of false failure. Replace sleeps with observable conditions, choose selectors that express stable semantics, and give each run isolated data. Virtualize only the dependencies whose real behavior is not the subject of the test, and maintain contract tests so the simulation does not drift from reality.
Measure the suite itself: duration, pass rate, flake rate, time to diagnosis, escaped defects, and coverage of critical risks. Test count is not a quality metric. Delete duplicated checks and scenarios that never influence a decision. Quarantine may protect the pipeline temporarily, but every quarantined test needs an owner and resolution date. The desired result is a fast signal engineers act on, a deeper signal before release, and evidence that maps failures to business risk.
A performance test is credible when another team can reproduce the conditions, see the same constraint, and use the result to make a safer capacity or release decision.— GARNO.TECH QA Team
Build a Regression System, Not a Test Collection
Regression testing should allocate feedback by risk and time. On every pull request, run deterministic unit, component, contract, and focused integration checks that finish quickly enough to remain part of development. After deployment to an ephemeral or shared environment, run critical API and end-to-end journeys. Schedule broader compatibility, migration, exploratory, and performance suites when the environment and decision justify their cost.
Quality gates need explicit consequences. A failed check on payments, permissions, data integrity, or a contractual performance threshold should stop promotion. A low-risk visual difference may create a review task instead. Treating every failure equally encourages teams either to ignore the pipeline or to weaken all gates. Define severity, owner, evidence, and override authority before pressure arrives.
Keep the suite aligned with the product. When a defect escapes, add the smallest durable test at the lowest effective level and ask why earlier feedback missed it. When a feature disappears, remove its tests. When a workflow changes, update test intent in the same change. A regression suite is an evolving risk model, not an archive of everything the team has ever checked.
Bring Functional and Performance Evidence Into Delivery
Performance checks belong at several points in delivery. A small benchmark can catch an algorithmic regression in a component. A short baseline scenario can compare a candidate build with the previous version. Larger average-load, stress, spike, and soak tests can run before a high-risk release or on a schedule against a controlled environment. Grafana k6 documentation recommends separating scenario logic from workload profiles and using thresholds as pass/fail criteria; that makes one business flow reusable across different questions.
A threshold should encode an agreed reliability goal, not yesterday’s accidental number. Segment it by operation: login and report generation rarely need the same latency target. Include custom metrics for completed business transactions and data correctness. Guard the test itself with abort conditions so an unexpected error flood or resource collapse does not turn an experiment into an outage.
After release, compare synthetic checks and real-user telemetry with pre-release evidence. Staging never perfectly reproduces production data, topology, background work, or dependency behavior. Use canary or progressive delivery to limit exposure, watch user-centered indicators, and roll back when the evidence contradicts the hypothesis. Continuous performance testing is not constant maximum load; it is a deliberate sequence of inexpensive early signals and deeper tests where uncertainty and impact are highest.
Choose a Partner by the Quality of the Decisions They Enable
A strong testing partner begins by clarifying the decision, not by proposing a favorite tool. They ask about revenue-critical journeys, traffic forecasts and evidence, SLOs, data and privacy constraints, architecture, deployment frequency, incident history, environments, observability, and who will implement recommendations. They distinguish a capacity assessment from a release gate, a bottleneck investigation, and an automation transformation because each requires different evidence.
Evaluate the proposed method. Will the workload model come from production analytics? Are test data and dependencies realistic? Can the team correlate client metrics with traces, database work, queues, and infrastructure? Do they state assumptions and limitations? Will they rerun after remediation? A polished dashboard without reproducible scripts, configuration, raw results, and a causal analysis has little long-term value.
Ask for deliverables that enable action: versioned tests, environment and data requirements, observability gaps, tested thresholds, a bottleneck narrative supported by timestamps, the safe operating envelope, remediation ordered by risk and effort, and a handover your engineers can run. Agree how production safety, third-party permission, sensitive data, and emergency aborts will be handled. The best engagement leaves the internal team with a better testing system and clearer decisions, not permanent dependence on an external operator.
Scalability is not a property that a tool can certify forever. It is a claim about a specific version, configuration, dataset, workload, and set of dependencies. The claim becomes useful only when it includes user-centered thresholds, a known safety margin, recovery behavior, and the evidence needed to reproduce the conclusion.
The practical loop is straightforward: model real journeys from production evidence; define success and stop conditions; prepare an interpretable environment; observe the full request path; find the first constraint; make one controlled improvement; and repeat the same experiment. Surround that loop with a regression system that gives fast feedback on every change and deeper evidence before consequential releases.
When these practices mature, testing changes the quality of planning. Product teams can discuss the cost of a campaign, engineers can prioritize the bottleneck that limits business capacity, and operators know how overload will appear and how the system should recover. That is the real output of load testing and QA automation: fewer unknowns when the stakes rise.
A Four-Stage Scalability Test That Produces Actionable Evidence
- /01Model user journeys and loadUse production analytics to define arrival rate, concurrency, request mix, payloads, data distribution, cache state, background work, peaks, and think time. State user-centered success thresholds before execution.
- /02Prepare reproducible conditionsRecord application and infrastructure versions, configuration, data, topology, generator location, and controlled dependencies. Validate scripts with smoke load and protect the test with stop conditions.
- /03Observe the complete request pathCorrelate business outcomes, percentiles, errors, and throughput with traces, logs, queues, pools, database work, caches, runtime pauses, infrastructure, and dependency latency.
- /04Find the limit, verify recovery, repeatRaise load in controlled steps, identify the first causal constraint, reduce load, measure recovery, verify data integrity, make one change, and rerun the identical test before publishing the safe operating envelope.
import http from 'k6/http';
import { check } from 'k6';

export const options = {
  scenarios: {
    checkout: {
      executor: 'ramping-arrival-rate',
      startRate: 20,
      timeUnit: '1s',
      preAllocatedVUs: 50,
      stages: [
        { target: 100, duration: '5m' },
        { target: 100, duration: '15m' },
        { target: 0, duration: '2m' },
      ],
    },
  },
  thresholds: {
    http_req_failed: ['rate<0.005'],
    'http_req_duration{operation:checkout}': ['p(95)<800', 'p(99)<1500'],
    checks: ['rate>0.995'],
  },
};

export default function () {
  const response = http.post('https://test.example.com/api/checkout', JSON.stringify({ sku: 'sku-42', quantity: 1 }), {
    headers: { 'Content-Type': 'application/json' },
    tags: { operation: 'checkout' },
  });
  check(response, {
    'checkout completed once': (res) => res.status === 201 && Boolean(res.json('orderId')),
  });
}
Why is average response time insufficient?
Why is average response time insufficient?
How realistic must the test environment be?
How realistic must the test environment be?
Should load tests run in production?
Should load tests run in production?
What should a load-testing report contain?
What should a load-testing report contain?
Which tests should be automated first?
Which tests should be automated first?
Need evidence that your application can handle growth?
Share the critical journeys, traffic evidence, SLOs, architecture, and release risk. We will design a reproducible test and turn the first constraint into an actionable plan.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
How to Choose a Mobile App Development Agency with Evidence
Evaluate mobile app agencies through product discovery, named-team evidence, native and cross-platform judgment, delivery, security, pricing, account ownership, release operations, support, and exit.
9 min read
05 Aug 2026
NestJS Backend Architecture: Security, Resilience, and Scalability
Build production NestJS backends with enforceable domain boundaries, server-side authorization, safe data and integration patterns, measured capacity, observable delivery, and sustainable ownership.
8 min read
05 Aug 2026
Scaling a NestJS Application from MVP to Enterprise
Evolve a NestJS MVP through modular boundaries, data and contract evolution, security, testing, observability, capacity, reliable delivery, and evidence-based service extraction.
9 min read
05 Aug 2026