/ 01
Aggregate-Shaped Access
Data read and changed together fits bounded documents, while critical queries avoid broad joins and have clear ownership.
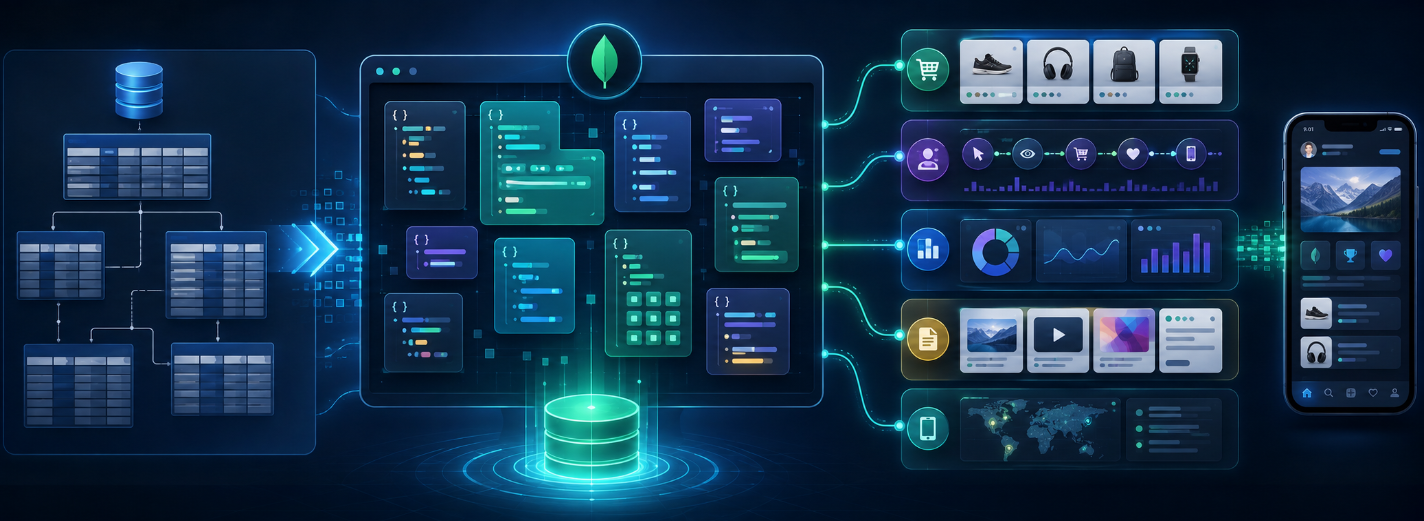
MongoDB is a strong choice when the product’s natural unit of work is a bounded document and its important reads can retrieve that unit without reconstructing it through broad joins. A catalog item with variable attributes, an order with a controlled set of lines, a user profile, a content page, a device configuration or an event-derived view can map cleanly to BSON. The fit comes from how data is read, changed and owned—not from a desire to avoid schema design.
Begin with a workload map. List critical commands and queries, filters, sort order, result size, read-to-write ratio, latency and availability targets, concurrency, volume, growth, retention, geography and regulatory constraints. Mark which facts change atomically, which relationships grow without bounds, which entities are queried independently and where stale data is acceptable. Include extreme tenants and historical records; an average document hides the skew that often determines capacity.
Compare credible alternatives on the same evidence. A relational database may better express dense relationships, cross-entity constraints, ad hoc joins and transactional reporting. Search, analytics, graph, time-series and object-storage workloads may need specialized systems. Polyglot storage is justified when each boundary has an owner and a reconciliation model; it is costly when every feature introduces another database.
MongoDB’s flexible document model lets related fields, nested objects and arrays evolve without a table migration for every optional addition. That can shorten responsible product iteration and represent controlled variation cleanly. It does not eliminate a schema: field names, types, identifiers, version interpretation and invariants still need contracts, validation, tests and migration rules.
Embedding can return related data in one read and make a change atomic within one document. Referencing is safer when a child exists independently, changes separately, participates in many-to-many relationships or can grow beyond a predictable bound. Deliberate duplication can serve fast reads, but the team must name the authoritative copy, propagation mechanism, acceptable staleness and reconciliation process.
Replica sets, managed Atlas operations and sharding provide paths for availability and growth. Their value depends on explicit read and write semantics, query-aware indexes, a suitable shard key, protected backups and applications that handle failover. Scalability is a system property; selecting MongoDB does not make an inefficient query, unbounded array or overloaded partition disappear.
Product catalogs are a classic fit when categories have different attributes but the application reads one product as a coherent record. Content systems can keep structured page blocks and localization together while validating each published shape. Profiles and preference stores work when the profile is bounded and owned as one aggregate. Device and asset platforms can store current state, configuration and a limited recent summary, with long histories moved to a better time-series or archival boundary.
Operational APIs and SaaS workflows can benefit when a case, subscription, order or workspace is the transaction and retrieval boundary. Event-driven systems may maintain MongoDB read models optimized for a screen or API, provided the source of truth, lag, replay and reconciliation are explicit. Geospatial, search and time-series capabilities can be useful within a MongoDB deployment, but should still be tested against specialist alternatives when they dominate the product.
Judge a use case by operations, not industry labels. “E-commerce” can mean a flexible catalog that fits documents, a financial ledger that favors relational constraints, a search index, and an analytics warehouse—all in one product. Draw the data authority and consistency boundary for each capability. State who writes it, how consumers read it, how duplication is repaired and how deletion propagates.
Prototype the hardest path with representative cardinality and skew. Include the largest embedded array, busiest tenant, common sort and range filters, concurrent updates, failed dependency, election and restore. Measure user latency, throughput, working-set pressure, index size, write amplification and operational effort. A convincing use case survives realistic failure and growth, not only a demo with a small uniform dataset.
Document flexibility can become inconsistency when teams introduce alternate names and types without version rules. Embedding can create oversized records, write contention and costly transfers when arrays or history grow without bounds. Referencing reintroduces application joins or aggregation work. Deliberate denormalization improves selected reads but makes propagation, stale copies and reconciliation part of the design.
Indexes are essential and not free. Each one uses storage and memory, adds write cost and must match real equality, sort and range patterns. Aggregation pipelines and $lookup can express sophisticated work, yet expensive online computation can exhaust resources as data grows. Multi-document transactions exist, but coordination cost and retry semantics mean they should protect real invariants rather than imitate a relational model everywhere.
Operational limits matter as much as modeling. Replica sets copy harmful writes as faithfully as good ones, so backups and tested restores remain necessary. Sharding adds routing, balancing, shard-key and failure complexity. Poorly distributed keys create hotspots; scatter-gather queries weaken the benefit. Managed Atlas reduces undifferentiated work, but the customer still owns topology, access, data policy, alerts, capacity, backup retention and recovery evidence.
MongoDB is a weak default when core work requires many arbitrary joins, strong constraints across numerous independent entities, complex transactional reporting, or query patterns are unknown and exploratory. It may also be excessive for a small stable dataset already served well by the current database. Migration cost, team capability, ecosystem fit and operating burden count alongside technical possibility.
MongoDB creates the most value when bounded documents match how the product reads, changes and owns data—and when the team can prove the indexes, consistency and recovery behind that model.— GARNO.TECH
Design compound indexes from important query shapes: equality filters, sort, range and projected fields. The ESR guideline is a starting hypothesis; validate it with explain, execution statistics and production-like data. Monitor keys and documents examined, response distribution, cache pressure, disk latency, connections, replication lag and slow operations. Remove redundant or unused indexes only after observing representative cycles.
Choose consistency from business consequences. Single-document writes are atomic. Use multi-document transactions for genuine cross-document invariants, with bounded work and tested retries. Configure read concern, write concern and read preference for acceptable staleness and loss. Drivers need timeouts, pool limits, backpressure and idempotent commands where outcomes may be uncertain after interruption.
Scale vertically while it remains economical, then shard when measured data size or throughput requires distribution. Evaluate shard-key cardinality, frequency, monotonic growth, hotspots and targeted query coverage with realistic skew. Plan zones, balancing, resharding implications and failure behavior. Capacity tests should include index builds, elections, backups, restores and concurrent workloads—not only steady-state reads.
Define RPO and RTO, configure backup frequency and retention, protect backup administration and rehearse restoration into an isolated environment. Monitor business journeys as well as cluster health. Every alert needs a threshold tied to impact, an owner and a runbook. Availability is the application’s ability to complete critical work, not simply the presence of healthy database processes.
A credible MongoDB partner begins with the workload and may recommend another database. Ask for experience with document modeling, schema validation, indexes and query plans, transactions, replication, sharding, Atlas security, backup restoration, observability and online migration. Review evidence from comparable volume, skew, availability and regulatory conditions instead of counting certifications or generic case studies.
The discovery should produce a workload map, target invariants, embed-versus-reference decisions, query and index catalogue, consistency matrix, capacity assumptions, security model, recovery plan, migration sequence, cost model and explicit trade-offs. Every major decision needs an owner and a way to validate it. Avoid proposals that promise “automatic scaling” without a shard-key analysis or flexible schemas without governance.
Require a production-shaped proof. It should use representative documents, common and worst-case queries, concurrent reads and writes, real identity, network restrictions, telemetry, backup and restore, and a dependency failure. For migrations, include bulk load, change capture, reconciliation, cutover, rollback and a single authority for writes. An importer reporting success is not data acceptance.
Keep ownership with the product team: infrastructure as code, repositories, Atlas organization and projects, credentials, encryption keys, alerts, dashboards, runbooks, schema decisions and cost visibility. Knowledge transfer should include an incident and restore exercise. The engagement succeeds when internal engineers can explain the data model, diagnose a slow journey, execute recovery and make the next schema change responsibly.
Use MongoDB when bounded document aggregates, controlled variation and measured distribution make the product simpler to build and operate. Choose another model when relational constraints, unpredictable joins or a specialist workload dominate. The responsible decision is made from access patterns, consistency, failure and ownership—not fashion.
Make the choice reversible. Prove one critical journey, define acceptance and exit thresholds, preserve a migration path and monitor the assumptions after launch. Data shape, volume and product behavior change; a healthy architecture can recognize when its original fit has weakened and adapt before the database becomes an organizational constraint.
Review the decision at known growth and product milestones. Compare observed query shapes, latency, incident burden, recovery evidence, infrastructure cost and development effort with the original assumptions. Retire unused indexes and duplicated projections, repair ownership gaps and reconsider storage boundaries when the evidence changes. Choosing MongoDB responsibly includes the ability to say when part of the workload should leave it.
const plan = await db.collection('orders')
  .find({ tenantId, status: 'pending' })
  .sort({ createdAt: -1 })
.explain('executionStats');Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
Choose polling, SSE, or WebSocket from product semantics, then design typed RxJS streams, reconnection, authentication, gap recovery, state reconciliation, memory safety, and production observability.
10 min read
A practical guide to planning a NestJS backend around business capabilities, API contracts, data ownership, security, integrations, background work, operations, and measurable delivery stages.
8 min read
A production guide to Angular design-system architecture and governance: ownership, semantic tokens, primitives, accessibility contracts, stable APIs, versioning, documentation, contributions, adoption, exceptions, and measurable outcomes.
10 min read