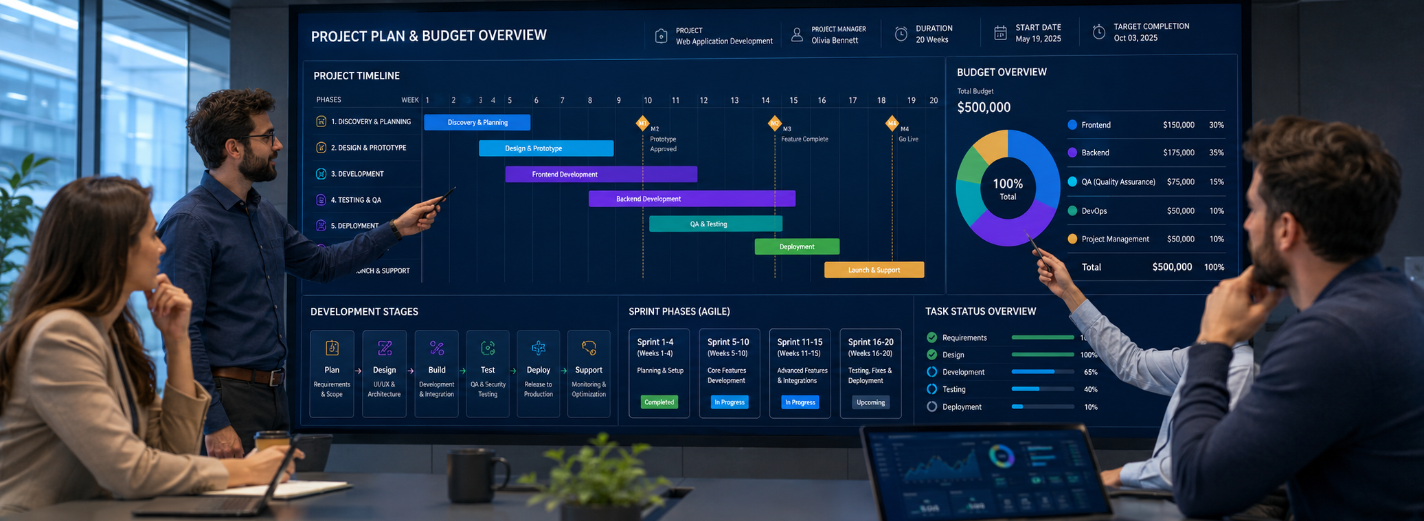
NestJS Development Cost: Scope, Team, Timeline, and Pricing
- NestJS
- backend development
- software development cost
- project estimation
- development team
- Node.js
NestJS Development Cost: Scope, Team, Timeline, and Pricing
A credible NestJS estimate is a model of work and uncertainty, not a price attached to a feature list. Two products with twenty endpoints can differ by an order of magnitude: one may be a private CRUD tool with one role and one database; the other a multi-tenant financial workflow with money movement, granular authorization, audit evidence, third-party providers, migration, recovery targets, and zero-downtime release constraints.
Start with a releasable outcome. Describe who completes which journey, what data changes, which systems participate, what must remain true, and how acceptance will be demonstrated. Then add the conditions that make the result production-ready: security, performance, availability, observability, environments, automated checks, deployment, documentation, and operational handover.
The estimate should expose what is known, assumed, excluded, and still uncertain. Use ranges until discovery or a technical spike produces stronger evidence. Record the confidence level and the events that would require re-estimation. A precise number built on vague requirements is less useful than a range whose assumptions can be inspected and managed.
What Actually Determines a NestJS Budget
Scope is more than screens and endpoints. Count actors, permissions, state transitions, business rules, reports, administrative operations, imports, notifications, scheduled work, and failure recovery. A simple action becomes expensive when it crosses several owners, must be idempotent, needs an approval trail, or cannot leave partial state.
Integrations carry disproportionate uncertainty. Provider documentation may omit rate limits, sandbox behavior, webhook duplication, reconciliation, regional constraints, or the approval process for production access. Estimate contract investigation, adapter design, test doubles, failure handling, observability, and joint testing—not only the happy-path HTTP call. Legacy data needs profiling, mapping, cleansing, trial migrations, reconciliation, and rollback.
Non-functional requirements turn directly into work. Latency and throughput targets affect queries, caching, queues, capacity tests, and infrastructure. Availability changes redundancy and release design. Security and compliance affect identity, authorization, secrets, audit evidence, data retention, environments, and review. Recovery objectives affect backups, replication, restore automation, and exercises.
Existing assets can reduce or increase the budget. Stable designs, decision-ready requirements, representative data, accessible owners, reusable platform services, and healthy code accelerate delivery. Incomplete specifications, hidden manual processes, shared databases, undocumented dependencies, and fragile deployment transfer their cost into discovery and risk. The same evidence should guide the choice between in-house, agency, and freelance NestJS team models.
- Product definition: discovery, journeys, roles, business rules, acceptance, design, data, ownership, exclusions, and decision availability determine how much ambiguity enters implementation.
- Technical depth: authorization, tenancy, workflows, transactions, migrations, reporting, real-time behavior, providers, legacy constraints, and failure recovery shape engineering effort.
- Delivery system: environments, test strategy, observability, CI/CD, release controls, documentation, support, stabilization, and knowledge transfer belong in the estimate.
- Risk and service targets: security, compliance, traffic, latency, availability, backup, recovery, retention, audit evidence, and operating ownership convert expectations into concrete work.
How Team Structure Changes Cost and Throughput
The cheapest-looking team is not necessarily the least expensive delivery system. Throughput depends on having the decisions, skills, access, and review capacity needed for the current stage. A small product may begin with a senior backend engineer, a product owner who can resolve scope, part-time QA, and shared platform or design support. A regulated or integration-heavy system may also need dedicated QA, DevOps or SRE, security expertise, data engineering, frontend capacity, and a technical lead.
Roles need not equal full-time people, but their responsibilities must exist. Someone owns architecture and trade-offs; someone accepts product behavior; someone verifies risk; someone owns environments, release, observability, and recovery. If these duties are omitted from the proposal, they do not disappear. They reappear as developer interruptions, blocked work, late defects, or founder dependency.
Team size has diminishing returns. Adding engineers increases communication, review, onboarding, environment demand, and dependency collisions. Parallel work accelerates delivery only when boundaries and decisions permit parallelism. Estimate effective capacity after ceremonies, support, reviews, incidents, leave, and cross-team coordination rather than multiplying headcount by nominal hours.
Rates matter, but compare them against the work system they buy. Senior engineers may cost more per hour while reducing architectural churn, clarifying unknowns early, reviewing critical code, and leaving operable decisions. Junior engineers can deliver valuable bounded work with good guidance; using them without review capacity simply moves cost into rework and risk.
Ask how the team estimates, demonstrates progress, tests integrations, handles scope change, reviews security, releases, responds to defects, documents decisions, and transfers knowledge. Inspect sample artifacts: a decision record, acceptance criteria, pull-request review, test strategy, dashboard, runbook, and handover plan. These reveal more about eventual cost than a role label.
Include client-side capacity in the estimate. Delayed answers, unavailable domain experts, slow legal or provider approval, missing test data, and inconsistent feedback create paid waiting and context switching. Name decision owners and response times. A vendor cannot compensate for a product organization that cannot decide what it is buying.
Build the Timeline from Dependencies and Evidence
A timeline is a dependency model. Start with a thin production-shaped journey that crosses the important risks: identity, authorization, one business rule, persistence, the hardest integration, telemetry, deployment, and rollback. This slice reveals whether environments, provider access, data, architecture, and team collaboration work before the project accumulates months of assumptions.
Plan milestones around usable evidence rather than technical layers. “Database complete” and “backend 70% complete” are difficult to accept. “An authorized operator can create, approve, and trace an order in staging, including a failed provider call” is reviewable. Each milestone needs entry conditions, acceptance evidence, exclusions, dependencies, and a named approver.
Sequence discovery and spikes before commitments that depend on them. Run provider and migration experiments early. Put security, performance, and recovery work beside the journeys they protect, not in a final hardening phase. Leave room for integration fixes, content and data preparation, user acceptance, release approvals, production observation, and stabilization.
Use a range, not a ceremonial deadline, while major uncertainty remains. Build the initial forecast from comparable work, decomposition, capacity, dependency lead times, and explicit risk. Distinguish effort from elapsed time: ten person-weeks cannot always become two calendar weeks by adding people, because decisions, integrations, and review form a critical path.
Update the forecast from observed throughput and newly resolved risks at agreed checkpoints. Show completed acceptance evidence, remaining scope, blocked dependencies, discoveries, and changes to assumptions. A forecast moving because reality became clearer is healthy; a date moving without an explanation is not.
Protect the release with conditions rather than optimism: migration rehearsal, performance threshold, unresolved defect policy, support readiness, monitoring, rollback, and decision authority. Stabilization is planned work, not a warranty-shaped void. Define how long the team observes production, which incidents are included, and when ownership transfers.
The most useful estimate is not the lowest or the most precise. It is the one that makes scope, assumptions, uncertainty, responsibilities, evidence, and stopping choices visible.— GARNO.TECH Engineering Team
Choose a Commercial Model That Matches Uncertainty
Fixed price works when the outcome, acceptance, interfaces, responsibilities, constraints, and change process are stable enough to price the remaining risk. The supplier must include a risk premium, so fixed price is not inherently cheaper. It is well suited to a bounded migration, audit remediation package, or clearly specified integration. It performs poorly when product discovery and implementation are still intertwined.
Time and materials fits evolving products and uncertain technical work because the customer pays for actual capacity and can redirect it as evidence changes. It requires transparent priorities, regular demonstrations, visible spend, strong product ownership, and the willingness to stop low-value work. Without those controls, flexibility becomes an unbounded queue.
A dedicated team buys sustained capacity and context for a roadmap. It can reduce handoffs and improve domain knowledge, but the customer still needs outcomes, priorities, governance, and periodic capacity review. A retained team should not become a reason to keep everyone busy regardless of value.
Hybrid structures are often practical: a short paid discovery produces a bounded release plan; a fixed milestone proves the largest assumption; time and materials then supports iterative delivery; a smaller retainer covers stabilization or ongoing improvement. The labels matter less than aligning who carries which uncertainty and who can make each decision.
Every contract should state deliverables, acceptance, exclusions, client dependencies, intellectual property, repository and cloud access, security duties, third-party costs, environments, release responsibility, defect handling, documentation, handover, termination, and the change mechanism. Link payment to reviewable evidence or agreed capacity, not ambiguous percentages of completion.
Compare proposals on total delivery boundary. One may exclude discovery, QA, DevOps, migration, monitoring, project leadership, and post-release support, then appear cheaper than another that includes them. Normalize the scope and assumptions before comparing rates or totals.
Control the Budget by Controlling Decisions
Budget control begins before development. Rank outcomes, define the smallest coherent release, identify the largest unknowns, and decide what evidence will unlock more investment. A prototype should answer a costly question; it should not quietly become production code. Set a contingency that corresponds to named risks rather than applying an unexplained percentage.
During delivery, keep one prioritized backlog with acceptance criteria and an explicit change policy. Review a short financial forecast beside product progress: spend to date, accepted outcomes, remaining range, blocked dependencies, risk movement, and expected operating costs. When scope changes, choose consciously among more budget, more time, exchanged scope, or a different quality or risk position.
Control work in progress. Too many concurrent features delay feedback and hide integration problems. Deliver vertical slices, demonstrate them in a representative environment, and close acceptance before opening more work. Track waiting time and rework causes; they often expose missing decisions, unstable interfaces, or review bottlenecks more clearly than individual productivity measures.
Include total ownership cost in the decision. Beyond implementation sit cloud services, observability, third-party fees, support, incident response, security updates, dependency maintenance, data retention, backups, recovery tests, compliance evidence, onboarding, and future change. Architecture that lowers the launch quote by transferring work to every later release is expensive.
Require ownership evidence before handover: repository and infrastructure access, reproducible environments, deployment and rollback, architecture decisions, API and data contracts, dashboards, alerts, runbooks, known limitations, credential rotation, backup restore, and a prioritized maintenance plan. Have the receiving team perform a release and recovery exercise with the delivery team observing.
The best budget is not the smallest approved number. It is the least investment that can produce a useful, secure, operable outcome and enough evidence for the next decision. A trustworthy estimate lets stakeholders see what they are buying, which risks remain, and how spending can stop without leaving an unusable half-system.
Need an evidence-based scope and estimate? Explore our NestJS development services for discovery, architecture, delivery, modernization, and operational handover.
A Four-Step Evidence-Based NestJS Estimate
- /01Define a Releasable OutcomeMap one complete journey, actors, rules, data, integrations, service targets, acceptance, exclusions, and client decisions instead of pricing a loose feature inventory.
- /02Retire the Largest UnknownsInvestigate providers, legacy data, security, performance, migration, and deployment. Use a technical spike only when its result changes architecture, scope, or confidence.
- /03Price the Whole Delivery BoundaryInclude product and technical leadership, implementation, QA, environments, security, observability, CI/CD, migration, release, stabilization, documentation, and handover.
- /04Forecast, Deliver, and Re-estimateState a range and assumptions, deliver a production-shaped milestone, compare accepted evidence and spend with the forecast, then update the remaining range openly.
Why should a NestJS estimate use a range?
Why should a NestJS estimate use a range?
Build a NestJS Estimate You Can Govern
Share the critical journeys, roles, rules, integrations, existing system, data, service targets, deadline drivers, team capacity, and known risks. We will define a releasable boundary, expose uncertainty, and produce a staged estimate with acceptance, ownership, and re-estimation checkpoints.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
WordPress Development for Business: Fast Publishing Without Fragile Growth
A production guide to WordPress architecture, block themes, custom functionality, WooCommerce, performance, Core Web Vitals, SEO, security, editorial governance and long-term ownership.
9 min read
04 Aug 2026
Angular Accessibility and WCAG 2.2: A Production Guide
Build accessible Angular applications through semantic HTML, keyboard and focus behavior, robust forms and dialogs, responsible ARIA, layered testing and durable team ownership.
11 min read
15 Sep 2026
Azure Cost Optimization After Migration: A Production Guide
Reduce Azure spend through workload evidence, rightsizing, autoscaling, commitments, data lifecycle, telemetry controls, Kubernetes economics and accountable FinOps.
11 min read
23 Aug 2026