/ 01
Small, Reversible Changes
Short-lived branches, focused checks, versioned artifacts, progressive delivery, and cleanup reduce batch size and make failure easier to locate, contain, and reverse.
Digital transformation is the ability to change how a business serves customers and operates, repeatedly, through software and data. A new application, cloud migration, or automation program may be part of that change, but none is transformation if every release still depends on handoffs, hidden configuration, manual approval, heroic recovery, and knowledge held by a few specialists.
DevOps provides an operating model for moving change from an idea to a safely operated outcome. Product, software, platform, security, data, support, and business stakeholders share feedback and responsibility across discovery, implementation, release, operation, and learning. Automation shortens repeatable steps; explicit ownership resolves decisions; observability shows what actually happened.
The objective is not maximum deployment frequency or a universal toolchain. It is a product system that can deliver small changes, verify their effect, contain failure, recover, protect users and data, and improve without exceptional effort. The right practices depend on the product’s risk, architecture, regulation, team capability, and commercial cadence.
Start with one valuable journey: opening an account, submitting an order, approving a claim, onboarding a tenant, or resolving a support case. Map the path from product decision to customer evidence, including queues, handoffs, environments, tests, approvals, deployments, and production validation. Measure work age, blocked time, change lead time, deployment frequency, failed-change recovery, change failures, rework, and the journey outcome. Use metrics to find the constraint, not to rank people.
Reduce batch size by delivering vertical slices that include behavior, data, integration, security, telemetry, release, and support. Short-lived branches, continuous integration, focused automated checks, versioned artifacts, and progressive delivery can shorten feedback and reduce the blast radius. A feature flag controls exposure; it does not excuse unfinished cleanup, indefinite branches, or untested combinations. Every flag needs an owner and removal condition.
A pipeline should produce traceable evidence. The team must know which source, dependencies, build environment, tests, policies, approvals, and configuration created an artifact; who promoted it; and how to reproduce or reverse the release. Keep high-consequence human decisions explicit while automating deterministic checks. Faster automation of an ambiguous process only makes the ambiguity arrive sooner.
Infrastructure as code turns environments into reviewable, versioned, repeatable definitions. Treat network, identity, compute, data services, secrets references, observability, policy, budgets, and recovery configuration as one product boundary. Plan and review effective changes before applying them, use narrow deployment identities, retain traceability, and separate environment values without copying architectures into unrelated scripts.
Reproducibility does not mean every environment is identical. Development, testing, staging, and production have different data, exposure, scale, cost, and access, but meaningful differences should be intentional and testable. Validate modules, scan for risky configuration, exercise deployments in representative conditions, and detect drift. Import or deliberately replace existing resources rather than pretending unmanaged state does not exist.
Build a platform only where repeated product needs justify it. Golden paths can provide supported templates, environments, identity, delivery, telemetry, and compliance controls while preserving escape paths for legitimate exceptions. Measure platform success through software delivery outcomes, task success, adoption, and developer experience. A portal that exposes more cloud complexity without reducing cognitive load is another dependency, not a platform product.
Reliability begins with critical user and operator journeys, not infrastructure uptime alone. Define service-level indicators and objectives for completion, latency, correctness, freshness, and availability where they matter. Use error budgets or another explicit policy to balance feature change with reliability work. A healthy container is insufficient if customers cannot authenticate, data is stale, or a provider silently rejects transactions.
Connect deployments to structured logs, metrics, traces, runtime profiles, business events, and configuration changes with stable identifiers. Alerts need a user consequence, owner, severity, response expectation, and runbook. Tune them against incidents and false positives. Telemetry that no one can access, interpret, or afford to retain does not create operability.
Design recovery before failure: timeouts, bounded retries with jitter, idempotency, backpressure, queues, circuit behavior, graceful degradation, rollback or safe roll-forward, backup restoration, failover, and reconciliation. Exercise representative dependency, zone, data, and deployment failures. Blameless learning still needs accountable corrective work: name the systemic cause, owner, acceptance evidence, and retest date.
Security becomes part of delivery when controls appear at the earliest responsible boundary and remain visible in production. Model assets, identities, data flows, trust boundaries, threats, and obligations with the product. Give workforce, pipeline, and workload identities separate, least-privilege access; protect secrets and signing material; validate untrusted input; govern dependencies; and preserve evidence for consequential changes.
Automate stable checks such as secret detection, dependency and artifact analysis, policy validation, infrastructure review, and selected application tests. Triage results by exploitability and consequence rather than forwarding every finding to product teams. Suppressions need a reason, owner, expiry, and review. Automation should block a defined unacceptable risk, not create an opaque queue that everyone learns to bypass.
Some decisions still require specialist judgment: architecture and threat review, legal or privacy interpretation, penetration testing, incident response, high-risk exceptions, and supplier assessment. Put these reviews early enough to change the design. In production, detect identity misuse, public exposure, control changes, vulnerable artifacts, data anomalies, and missing telemetry; rehearse containment and recovery across team boundaries.
DevOps fails when it becomes a team that receives tickets from developers and throws production incidents back over the wall. Product teams should own the behavior and operation of their services within clear boundaries. Platform teams own shared capabilities as products. Security supplies policy, expertise, detection, and response partnership. Support and operations bring user and incident evidence into planning. Leaders decide priority and residual risk.
Make the interfaces explicit: service ownership, service objectives, on-call roles, escalation, platform support, release authority, data stewardship, vendor responsibility, and incident command. Provide client and team access to source, environments, dashboards, runbooks, and decisions. Rotate operational participation and use pairing or game days to transfer judgment without forcing every engineer to master the entire estate.
Psychological safety matters because early warnings often arrive as uncertainty: “this migration may not finish,” “the alert is unreliable,” or “the vendor outcome is unknown.” Reward surfacing weak signals and changing the plan. Pair that safety with accountability for follow-through. Collaboration is visible when a signal reaches an owner and changes a decision, not when more people attend the same meeting.
Cloud elasticity changes the shape of cost; it does not make cost self-managing. Assign ownership, tagging or equivalent allocation, budgets, anomaly detection, and review cadence before scaling. Connect spend to useful demand such as an active tenant, processed order, document, inference, or API customer. Include licences, third parties, observability, data transfer, backups, support, and engineering effort in the total cost.
Optimize from evidence: remove abandoned resources, right-size from telemetry, schedule nonproduction use, tier data, bound autoscaling, control log volume and cardinality, and repair inefficient code or queries. Use reservations or commitments for stable understood demand. A cost reduction that removes recovery capacity, security evidence, or production visibility is a risk decision and needs an accountable owner.
Test cost under exceptional modes. Backfills, retries, incident logging, load tests, regional recovery, data export, and sudden traffic may produce a different unit cost from normal operation. Set guardrails that inform or constrain changes without automatically breaking a critical journey. FinOps becomes useful when finance, product, platform, and engineering share definitions and can act on the result.
Digital transformation becomes durable when every software change carries evidence, ownership, a safe path to production, and a tested path back to control.— GARNO.TECH
Begin with one product, one journey, and one measurable constraint. Establish the baseline, owner, desired outcome, guardrails, and review date. The first intervention might be a reproducible build, reliable test stage, versioned environment, deployment telemetry, smaller batch, restore exercise, or clarified incident ownership. Choose the smallest control that changes the observed bottleneck.
Deliver the improvement as a thin operational slice and use it under real work. Document the paved path, exceptions, support model, and client ownership. Measure whether change lead time, recovery, failure, rework, task success, reliability, developer experience, or product outcome improved. Do not declare success because a pipeline ran or a tool was installed.
Expand only after learning. Standardize what several teams genuinely repeat; keep product-specific variation close to the product. Retire old paths, credentials, scripts, and approvals when the replacement is proven, or complexity doubles. Provide coaching, pairing, decision records, and accessible runbooks so capability moves into teams rather than remaining with a transformation program or supplier.
DevOps makes digital transformation sustainable by connecting change with operation. Small batches make learning affordable; executable environments reduce undocumented variation; delivery controls create traceability; observability reveals outcomes; security and recovery protect the journey; shared ownership turns evidence into action; and cost signals keep the model economically honest.
The work is never finished because products, threats, platforms, teams, and markets change. Review the system when delivery slows, incidents repeat, costs detach from demand, controls become ceremonial, or teams route around the platform. Preserve the principles while changing the implementation.
The durable result is not a pipeline, cloud account, platform portal, or DevOps job title. It is an organization able to make a consequential software change, explain its assumptions, release it safely, see what happened, recover when necessary, and improve the next attempt.
Share the critical journey, delivery path, infrastructure, dependencies, deployment and incident history, security controls, cloud costs, team boundaries, and current metrics. GARNO.TECH can identify the governing constraint and define a bounded improvement with ownership, acceptance evidence, and knowledge transfer.
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
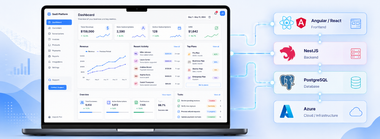
Design NestJS APIs around business boundaries, authoritative contracts, REST and GraphQL trade-offs, asynchronous communication, security, reliability and operating ownership.
9 min read
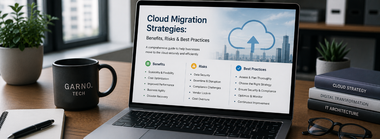
Choose cloud migration strategies by business outcome, application evidence, data and dependency risk, security, resilience, operating cost, and team readiness.
8 min read
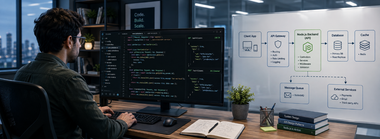
Evaluate NestJS against product complexity, team skills, security, integrations, scale, delivery pace, and operating costs before choosing it for a business backend.
9 min read