Azure Landing Zone Architecture: A Production Guide
- Azure landing zone architecture
- azure
- architecture
- development
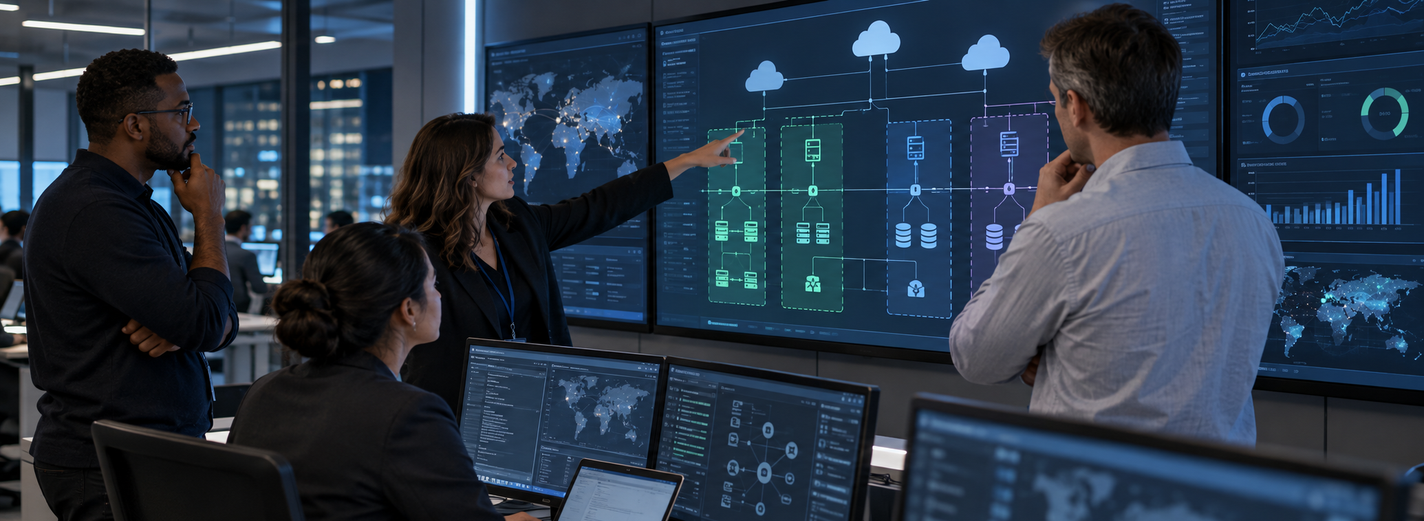
An Azure landing zone is the governed foundation into which workloads are deployed. It establishes boundaries for ownership, identity, connectivity, policy, telemetry, recovery and cost before application teams face production pressure. It is not a fixed diagram or a collection of fashionable Azure services. Its value is the repeatable path by which a team can receive an environment, deploy safely, operate a workload and prove compliance with business requirements.
Begin with the organization and workloads. Map business units, regulated or regional boundaries, platform and application teams, critical journeys, data classes, connectivity, availability and recovery objectives, cost allocation, deployment model and support responsibilities. Decide which controls must be inherited centrally, which belong to each workload and how exceptions expire. Use Azure Landing Zone guidance and the Well-Architected pillars as references, then tailor the implementation to actual scale and capability.
Define success operationally: time to onboard a workload, policy compliance, privileged-access review, deployment success, telemetry coverage, recovery evidence, cost attribution and exception age. A landing zone is ready when a representative team can use it through documented automation and the platform team can support it—not when resources merely exist.
What a Production Landing Zone Provides
The foundation should provide a clear tenant and management hierarchy, subscription vending, identity and privileged-access patterns, network and DNS connectivity, policy guardrails, central security and operational telemetry, resource organization, budgets, automation and an onboarding contract. It should also define incident escalation, platform maintenance, recovery responsibilities and how workload teams request an exception or new shared capability.
Separate platform services from workload responsibilities. The platform team can operate connectivity, policy, common logging and account vending while a workload team owns its application authorization, data lifecycle, service objectives, deployment and repair. Shared responsibility must be explicit at every boundary. “The cloud team handles security” is not an operating model.
Prove the foundation with a representative workload. Follow identity from developer to pipeline and runtime, trace traffic and DNS, deploy with infrastructure as code, trigger a policy violation, inspect logs and cost, exercise an incident and remove the workload. The test reveals whether documentation, permissions and support paths match the architecture.
Design Management Groups and Subscriptions by Boundary
Management groups organize policy and access inheritance; they should express durable governance differences rather than mirror a changing org chart. Keep the hierarchy shallow. Common distinctions may include platform, landing-zone workloads, sandbox and decommissioned subscriptions, with additional branches only for genuine regulatory, sovereignty or operating requirements. Test inheritance and exemptions before broad assignment.
A subscription is a governance, billing, quota and blast-radius boundary. Separate workloads or environments when they need distinct owners, policies, budgets, lifecycle, limits or incident isolation. Avoid one enormous production subscription that couples unrelated teams, and avoid a subscription per tiny component that multiplies administration. Record the decision rule so growth produces consistent boundaries.
Automate subscription vending with an owner, purpose, environment, cost center, contacts, policy set, network intent, logging destination, budget and expiry where relevant. Quotas and regional availability are capacity constraints, not afterthoughts. The offboarding path must archive evidence, transfer or delete data, remove routes and identities, settle commitments and close spend.
Use Resource Groups for Lifecycle and Identity for Trust
Use resource groups for resources that share lifecycle, deployment, access and operational ownership. They are not folders, and they do not create network or failure isolation. Place a resource according to who changes, monitors, pays for and deletes it. Apply names and tags for discoverability and automation, but use policy and source-controlled inventory when correctness matters.
Anchor workforce and workload trust in Microsoft Entra ID. Prefer groups over direct user assignments, managed identities over stored application secrets and narrowly scoped roles over broad contributor access. Protect privileged roles with strong authentication, time-bounded elevation, approval where justified and monitored emergency accounts. Review guest users, service principals, stale credentials and role assignments on a defined cadence.
Design custom roles only when built-in roles cannot express the responsibility, and test their data and control-plane permissions. Separate pipeline deployment authority from human administration and production support. Every identity needs an owner, purpose, scope, credential or federation method, review date and revocation path.
Make Connectivity, DNS and Security Operable
Choose network topology from traffic and ownership rather than a default picture. Hub-and-spoke or Virtual WAN can centralize shared connectivity at different scales, but both require route, firewall, DNS and operations design. Map ingress, egress, east-west and hybrid flows, expected throughput, latency, availability, inspection and cost. Assign owners for address space, routes, private endpoints, certificates and external allowlists.
DNS is part of the application dependency graph. Define public and private zone ownership, forwarding, resolver availability, split-horizon behavior, record lifecycle and hybrid name resolution. Private connectivity adds operational dependencies; it does not replace identity, authorization or data protection. Test resolution and routes from every relevant environment, including failure paths.
Reduce blast radius with segmentation and explicit trust, then make the controls observable. Protect administrative access, restrict uncontrolled egress where the threat model requires it, log material network decisions and rehearse emergency changes. Avoid a central inspection design whose capacity, availability or ownership is weaker than the workloads it protects.
Roll Out Policy and Telemetry as Products
Policy translates governance outcomes into preventive, auditing or remediation controls. Start with a small set tied to material risks: allowed regions, required diagnostics, public exposure, approved resource types, encryption, tags or protected configurations. Deploy definitions as code, test in a representative scope, begin with audit where appropriate, inspect false positives and then enforce. Every exemption needs rationale, owner, scope, compensating control and expiry.
Central telemetry needs an operating purpose. Decide which activity, identity, security, network, platform and workload signals are collected; who can query them; retention and residency; detection and response ownership; and cost limits. Route actionable alerts to a staffed path with severity and repair instructions. Logs that nobody can access during an incident provide little assurance.
Measure the platform itself: onboarding time, failed deployments, policy compliance and exemptions, privileged changes, logging gaps, incident response, recovery tests and cost allocation. Treat policy packs, dashboards and alert rules as versioned products with tests and release notes. Changes to inherited control can affect every workload and need a staged rollout.
Isolate Environments and Reproduce Them with IaC
Production and nonproduction need boundaries proportionate to risk. Separate identities, data, secrets, network paths, policies, budgets and deployment approvals where an accidental change could cross into production. Do not copy sensitive production data into development by default; use generated, masked or controlled subsets with retention and access rules.
Represent management hierarchy, policies, role assignments, connectivity, shared services, diagnostics and subscription vending as modular infrastructure as code. Pin versions, review plans, protect state, test modules and promote changes through representative environments. Detect drift and decide whether to reconcile or document an emergency exception. Console changes require the same evidence and follow-up as code changes.
Design upgrade and rollback paths for the platform modules. A breaking policy or route can have a larger blast radius than an application release. Use versioned interfaces, staged adoption, compatibility windows and consumer communication. Rebuilding a nonproduction slice from source is a valuable proof that the landing zone is reproducible.
Control Platform Complexity with an Onboarding Contract
Platform complexity is justified only when it removes repeated workload risk or toil. Avoid adding firewalls, clusters, gateways, regions, custom roles or policy layers without a named requirement, owner, service objective and operating budget. Managed services reduce some duties but introduce quotas, product lifecycle, vendor dependency and new failure modes. Compare the simplest credible option against expected scale.
Publish an onboarding contract: inputs a workload supplies, foundation capabilities it receives, controls it inherits, responsibilities it retains, evidence needed for production, support path, cost model and exception process. Provide paved paths for common workload shapes while permitting an evidence-based escape. Developer experience is a control because teams route around a platform they cannot understand or use in time.
Review the landing zone after representative onboardings, incidents, audits, major Azure changes and organizational growth. Retire unused shared services and consolidate rules that no longer express a distinct risk. Architecture stays coherent through named decisions and removal, not continual accumulation.
When Independent Azure Expertise Is Useful
Independent review is useful when the design crosses several business units or regions, inherits a fragile tenant, serves regulated data, introduces complex hybrid connectivity, or must recover from inconsistent policy and access. It also helps before broad enforcement, a major migration or a platform-team handover, when one mistake could affect many workloads.
Ask the reviewer to test real scenarios and artifacts: hierarchy and inheritance, a subscription request, privileged access, deployment, private DNS, log retrieval, policy exemption, cost allocation, incident response and offboarding. The output should be a prioritized decision register with evidence, business consequence, owner, acceptance criteria and safe rollout—not a generic maturity score.
GARNO.TECH can assess an existing foundation, design a minimum viable landing zone, implement versioned modules or help a platform team onboard its first representative workload through Azure cloud development. Ownership, repositories and accounts remain client-controlled, with knowledge transfer and exit designed from the beginning.
- Boundaries: define tenant, management-group, subscription and resource-group rules from governance, lifecycle, ownership and blast radius.
- Identity: use groups, managed identities, least privilege, time-bounded elevation, emergency access and scheduled reviews.
- Connectivity: map traffic and DNS, capacity, inspection, hybrid dependencies, availability, cost and accountable operators.
- Guardrails: deploy versioned policies and exemptions gradually, with telemetry, owners, expiry and tested remediation.
- Automation: vend subscriptions and shared controls through reviewed IaC, protected state, module tests, drift handling and rollback.
- Onboarding: prove deployment, operations, recovery, cost allocation, exception handling and offboarding with a representative workload.
What is an Azure landing zone?
What is an Azure landing zone?
Does every company need a complex enterprise landing zone?
Does every company need a complex enterprise landing zone?
How should Azure subscriptions be separated?
How should Azure subscriptions be separated?
Should policy enforcement begin immediately?
Should policy enforcement begin immediately?
How do we know the landing zone is production-ready?
How do we know the landing zone is production-ready?
Build a Secure Azure Foundation Before Workloads Scale
Share the tenant structure, current subscriptions, identity requirements, connectivity, workload types, policy obligations and operating model. GARNO.TECH will identify the minimum viable foundation and a representative onboarding proof with clear ownership, acceptance and rollout.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
NestJS Backend Architecture: Security, Resilience, and Scalability
Build production NestJS backends with enforceable domain boundaries, server-side authorization, safe data and integration patterns, measured capacity, observable delivery, and sustainable ownership.
8 min read
05 Aug 2026
Custom WordPress Development: When Control Creates Business Value
A practical guide to choosing custom WordPress development for distinctive content, conversion journeys, integrations, WooCommerce, performance, security, and maintainable growth.
9 min read
02 Aug 2026
How to Evaluate an Angular Development Partner
A practical framework for selecting an Angular partner through product fit, production evidence, architecture, testing, accessibility, security, delivery controls, team integration, lifecycle economics, ownership, and exit.
8 min read
31 Jul 2026