/ 01
Before a Launch or Demand Event
Validate the most valuable journeys against forecast traffic, peak shape, scaling delay and failure thresholds before demand puts customers, operations and revenue at risk.
Real workload · correlated telemetry · safe execution · repeatable comparison
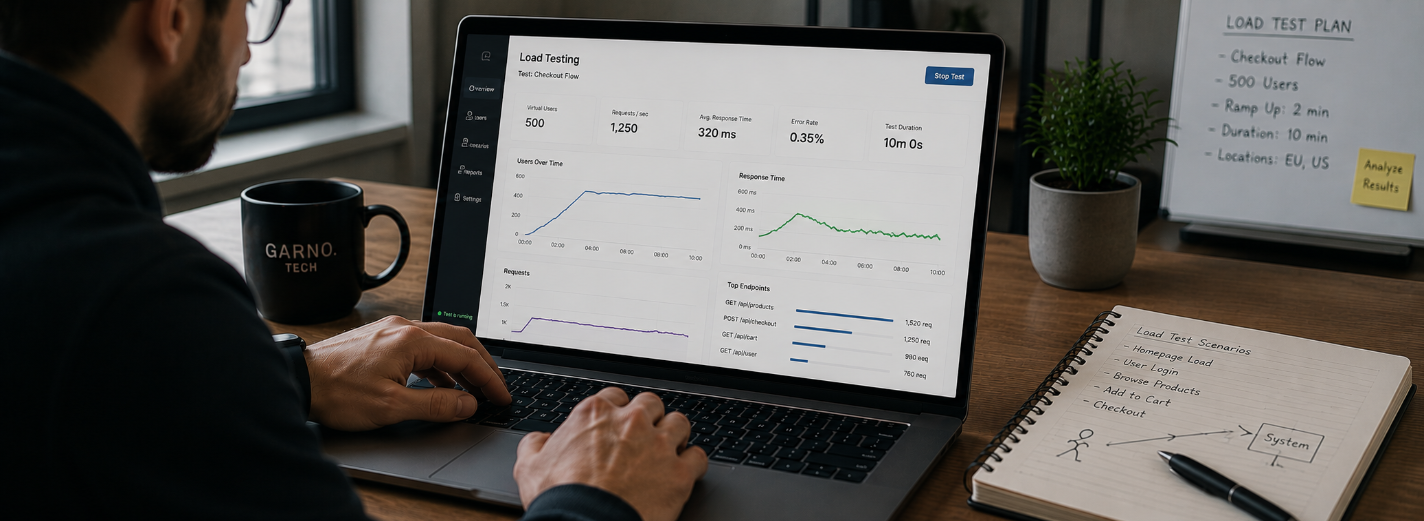
A load test is useful when it changes a decision. It can show whether checkout will meet a latency objective during a campaign, how many jobs a queue can drain before backlog grows, which dependency saturates first, whether autoscaling responds in time, or whether a recent change introduced a regression. A large request count without a workload model, system telemetry, and explicit pass or stop conditions produces theatre rather than capacity evidence.
We design performance tests around critical business journeys and the production system that serves them. The engagement connects client-side results with application, database, cache, queue, network, infrastructure, and external-dependency signals. It ends with reproducible scripts, bounded conclusions, prioritized actions, and a comparable retest—not an unsupported promise that the platform can handle an arbitrary number of “users.”
An average-load test validates ordinary sustained demand and creates a baseline for later comparison. A stress test raises demand beyond the expected peak to expose degradation and recovery. A spike test applies a sudden surge to examine queueing, autoscaling, throttling, and admission control. A soak test holds representative load long enough to reveal memory growth, pool exhaustion, log or storage expansion, scheduled-work collisions, and slow leaks. A breakpoint or capacity test increases pressure in controlled steps until an agreed objective fails. A small smoke run should prove the script and environment before any larger test.
The business question determines the mix. A launch may need expected traffic plus a safe stress margin; a ticket release may need a sharp spike; a billing platform may need an endurance run that crosses scheduled jobs; an API change in CI may need a short regression test. Protocol-level scripts efficiently generate backend traffic, while browser measurements capture rendering and user experience but cost more to scale. A hybrid approach often uses protocol traffic for volume and a small number of browser journeys to observe the real frontend.
“Concurrent users” is not a workload until it includes arrival rate, journey mix, pacing and think time, session length, data distribution, cache state, geography, device and network assumptions, authentication, retries, background work, and test duration. We derive these from production analytics, forecasts and product events where available, then document uncertainty. The result is an open or closed workload model that the team can inspect, challenge, and rerun.
A responsible test begins with authorization and an environment decision. A representative non-production environment is preferable when it reproduces topology, configuration, data scale, quotas, integrations, observability and scaling behavior closely enough for the question. Production testing may be necessary to validate the production path, but only with explicit written approval, named operational owners, a reviewed scenario, a change window, customer-impact controls, provider coordination, live monitoring, stop conditions, recovery steps, and a communication plan.
Prepare synthetic or masked data that preserves cardinality and query shape without exposing personal or regulated information. Create test accounts, idempotent setup and cleanup, controlled credentials, network access, IP allowlists, capacity for the load generators, and a way to distinguish test traffic in logs. Confirm that email, SMS, payments, identity checks, webhooks, analytics, fraud engines and other third parties permit the traffic. Stub or model a dependency when direct load is prohibited, expensive, unsafe, or would corrupt evidence.
Define guardrails before execution: maximum request or transaction rate, error and latency thresholds, infrastructure saturation, queue depth, database pressure, cost ceiling, customer signals, test duration, and the person authorized to stop. Run a smoke check, calibrate the generators so they are not the bottleneck, verify clocks and telemetry, and capture an idle baseline. High-volume tests can create real incidents; safety is part of the experimental design, not a disclaimer added afterward.
Measure the offered load and completed work separately. Record iterations, requests, transactions, bytes, active sessions, arrival rate, throughput, retries and dropped work. Report latency as a distribution—such as median, p90, p95 and p99—by journey and request, because an average can hide a damaging tail. Track errors by class and business meaning: a fast 429, a timeout, a validation rejection, a duplicate transaction and a silent wrong response require different decisions. Validate important response content so an error page with HTTP 200 does not count as success.
Correlate client observations with server evidence across application traces, CPU, memory, garbage collection, thread or event-loop pressure, connection pools, container restarts, autoscaling, network limits, cache hit rate, database query latency and locks, storage throttling, queue depth and age, downstream calls, rate limits and circuit breakers. Tag runs, versions, scenarios and requests with stable identifiers. Time-aligned signals turn “the test became slow” into a causal hypothesis about the first constrained resource and the propagation that followed.
Observe recovery as deliberately as the ramp. After demand falls, do queues drain, pools and memory normalize, autoscaling contract safely, retries stop, circuit breakers close, caches recover, and scheduled work resume? A service that reaches a high peak but needs manual repair has not demonstrated resilient capacity. We compare results only inside stated boundaries: environment, version, data, workload mix, generator locations, duration, cache state and thresholds. Capacity is a conditional operating envelope, not a permanent property of the system.
You receive a decision record that states the question, tested architecture, versions, assumptions, exclusions, risks and validity limits. The workload model describes journeys, arrival or concurrency model, pacing, data, authentication, warm-up, ramp, steady state, spike or stress stages, recovery and success criteria. Reusable scripts and configuration live in source control with setup instructions, safe parameters, test-data handling, secret expectations and generator requirements. This lets the team repeat the experiment after code, infrastructure or traffic changes.
The results package includes client metrics, business checks, time-aligned system telemetry, failed-request samples, saturation evidence, recovery behavior, anomalies and confidence limits. We separate observation from inference and mark gaps where telemetry cannot prove a cause. Recommendations are ranked by expected impact, supporting evidence, effort, risk and how each change should be verified. The highest-value fix may be a query or cache policy, but it may also be admission control, queue bounds, timeout alignment, autoscaling lead time, payload reduction, data partitioning, or a clearer service objective.
A baseline becomes valuable through comparison. We preserve the scenario and relevant environment state, then rerun the agreed stages after changes. The comparison covers throughput, percentile latency, errors, resource demand, recovery and cost per useful transaction rather than celebrating a single improved chart. Results never claim capacity beyond the tested envelope, and they distinguish system limits from generator limits, third-party throttling, nonrepresentative data and environmental differences.
The test report should enter an engineering decision loop. First fix measurement gaps and correctness failures; performance numbers are unreliable when responses are wrong or traces disappear. Then address the earliest limiting constraint rather than tuning every visible metric. Recheck the change with the same scenario, inspect whether the bottleneck moved, and repeat until the required objective is met or the economic tradeoff becomes clear. Record accepted limits and operational controls for traffic beyond them.
Embed small, stable tests at meaningful delivery points. A brief performance regression can guard a critical API in CI; a scheduled baseline can reveal gradual drift; a release-candidate test can validate infrastructure and configuration; larger stress, spike and soak exercises can run before high-risk events. Thresholds should express service objectives and known budgets, fail on relevant percentile latency, errors or throughput, and avoid unstable gates built on noisy environments. Review scripts as production assets when journeys, authentication, data, APIs or traffic change.
Your team may implement the recommendations, or GARNO.TECH can support a separately scoped product scaling initiative, NestJS backend improvement, or Azure architecture change. Implementation remains optional. The load-testing engagement is complete when the decision is supported by reproducible evidence, the team understands the boundaries, and agreed improvements have a credible verification path.
Share the critical journey, expected demand, current architecture, available environment, telemetry and the decision the test must support. We will define the smallest responsible scope that can produce reusable evidence.