/ 01
Explore Beyond Known Scripts
Use observation and product judgment to follow unexpected behavior, combine states, vary data, question ambiguous expectations, and investigate high-risk workflows beyond predefined checks.
Manual QA is valuable because software risk is not fully enumerable. A scripted check can confirm a known expectation; a skilled tester can notice that the expectation is incomplete, follow an unusual interaction, question an ambiguous message, compare behavior across roles, and investigate a result that is technically valid but dangerous or confusing for a user.
The work should reduce uncertainty, not produce activity statistics. Before testing, define the release decision, critical journeys, recent changes, affected data and integrations, supported platforms, known weak points, and consequences of failure. Testing depth follows risk: a cosmetic inconsistency in a rarely used view does not deserve the same attention as a permission leak, incorrect charge, lost draft, broken recovery flow, or inaccessible primary action.
The useful outputs are decision evidence: a risk-ranked test approach, an explicit coverage map, reproducible defect reports, retest and regression status, blocked scope, unresolved findings, and a reasoned recommendation. A recommendation does not replace product ownership. It gives accountable people a clear view of what was observed, what was not tested, and which residual risks they would accept by releasing.
Bring manual QA in early when requirements are still becoming concrete, not only after development “finishes.” Reviewing examples, states, permissions, error behavior, analytics, and acceptance criteria can expose contradictions before code makes them expensive. During implementation, focused checks on completed vertical slices shorten feedback; before release, regression and exploratory sessions evaluate the assembled product and its operating conditions.
Manual testing is especially useful for new behavior, complex multi-role workflows, irregular integrations, usability and accessibility questions, browser or device variation, data migration, interrupted journeys, and incidents that cannot yet be reproduced reliably. It also helps when an internal team needs temporary release capacity or an independent view of a high-consequence change.
A short timeline does not require pretending that everything was covered. Rank flows by customer harm, revenue, legal or security consequence, usage, blast radius, change size, defect history, and recoverability. Test the most consequential combinations deeply, sample lower-risk variants, and state exclusions. If the build, environment, accounts, data, or dependency is unavailable, record the blocked evidence rather than counting the intended test as passed.
A test plan should be proportionate and usable. It names objectives, in-scope and excluded behavior, risks, acceptance sources, environments, data, roles, platform matrix, techniques, entry and exit conditions, reporting cadence, owners, and assumptions. For a focused release this may be a concise checklist and risk map; a regulated or long-running program may need traceable cases and formal evidence.
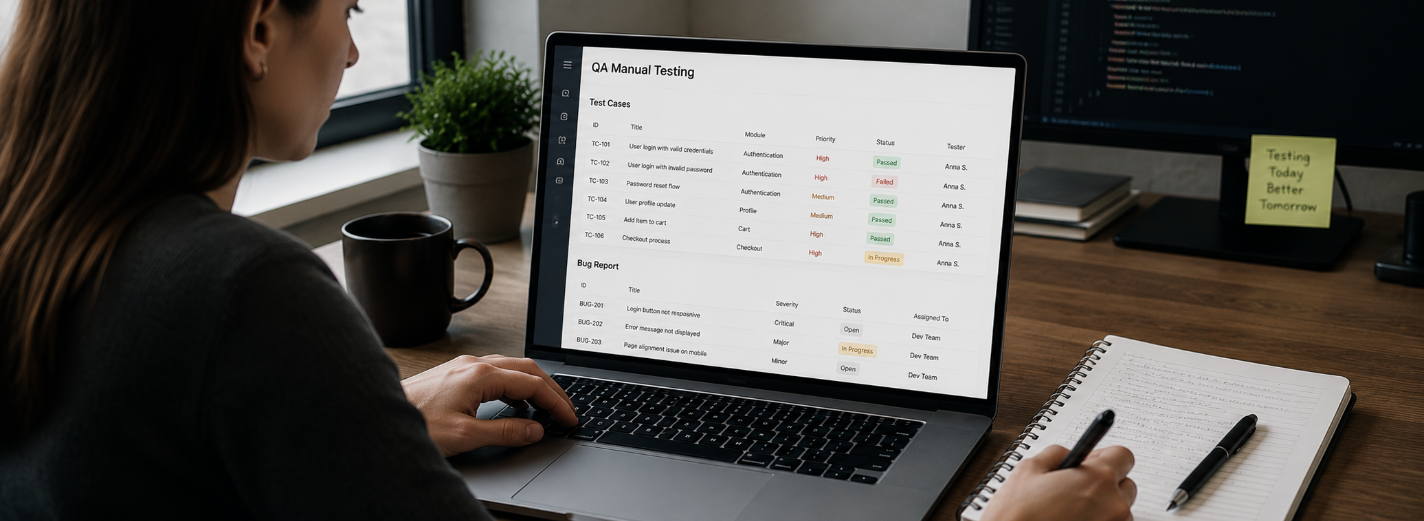
A useful defect report lets another person make progress without a meeting. It contains a precise summary, build and environment, account or role, preconditions, minimal reproduction steps, expected and observed behavior, frequency, supporting screenshots, video, logs or request identifiers, and any safe workaround. Severity describes impact; priority reflects the business decision and belongs to triage. Sensitive customer data, credentials, and unnecessary payloads stay out of tickets and media.
The final summary distinguishes facts from judgment. It records executed and passed coverage, failures, blocked and skipped areas, fixed and retested defects, open findings by consequence, changes made late in the cycle, known environment limitations, and the regression performed after fixes. The release recommendation—go, hold, or limited rollout—states its reasoning and conditions, such as disabling one feature, monitoring one metric, or completing a named check before wider exposure.
Functional testing verifies rules, states, calculations, permissions, integrations, and end-to-end outcomes against agreed expectations. It covers success and failure, not only a happy path. Exploratory testing uses a charter, time box, observations, and adaptive investigation to discover risks that predefined cases did not anticipate.
Regression testing checks the changed capability, its dependencies, and stable critical journeys after a release candidate or fix. The suite should follow impact and history rather than grow forever. Compatibility testing examines chosen browsers, operating systems, devices, screen sizes, input modes, network conditions, and platform behavior. Usability and accessibility checks look at comprehension, feedback, recovery, focus, keyboard use, semantics, text scaling, contrast, reduced motion, and assistive technology on real tasks.
API and integration testing evaluates authorization, validation, state transitions, error contracts, idempotency, timeouts, duplicates, ordering, and dependency degradation. Data testing examines migrations, permissions, imports, exports, rounding, timezone behavior, and reconciliation. Security review, penetration testing, load testing, and formal accessibility audit require their own methods and expertise; a few manual checks must not be presented as substitutes.
The boundary between manual and automated work is economic and epistemic. Automate a stable, frequent, deterministic check when fast repeatable feedback justifies maintenance. Keep human exploration for new, changing, ambiguous, visual, cross-system, or judgment-heavy behavior. A strong strategy lets automation preserve known expectations while testers spend attention on uncertainty.
Testing starts with shared context: a traceable build, release intent, change set, acceptance sources, environment health, roles, accounts, data, feature flags, integrations, and known incidents. The tester joins refinement or demos where questions can still change the product. Developers explain architecture and risky change; QA explains observed behavior and coverage. Neither side turns uncertainty into blame.
Report findings in the team’s existing workflow and discuss high-impact issues immediately. A defect is ready for triage when the behavior is reproducible or the uncertainty is clearly bounded, evidence is safe and sufficient, and consequence is explained. Developers can then reproduce, locate, fix, or challenge the expectation. Duplicate and related findings should be linked so the team sees a pattern rather than a pile of tickets.
Retest the exact fix in the declared build and environment, then check nearby behavior based on the failure mechanism. A calculation defect may affect reports and exports; a permission defect may affect every object route; a UI-state fix may affect navigation and restore. Closing a ticket because code was merged is not verification. If reproduction disappears without an understood cause, record the uncertainty instead of declaring it solved.
Use a short feedback loop throughout the release. Daily or milestone updates name completed scope, new risks, blocks, defect movement, and decisions needed. The final recommendation should contain no surprise that could have been surfaced earlier.
A coverage matrix translates “works on supported platforms” into inspectable choices. Start with product analytics, contractual commitments, market and language, user importance, revenue and permission paths, operating systems, browsers, devices, screen sizes, input modes, assistive technologies, hardware capabilities, network conditions, and recent platform-specific changes.
Do not multiply every dimension blindly. Use equivalence and risk to select representative combinations, then deepen coverage where impact or technical divergence is high. A responsive web flow might need viewport and input variation more than dozens of browser patch versions. A mobile camera, Bluetooth, payment, or background workflow may need physical models and operating-system states that a simulator cannot reproduce.
Record which combinations receive full, focused, sampled, or no coverage and why. Include the actual build, browser engine, OS version, device class, locale, permissions, connectivity, and relevant configuration in evidence. Revisit the matrix as audience data, support commitments, framework behavior, and incident history change. “All devices” is not a testable claim.
Environment fidelity matters as much as platform choice. Test with production-shaped roles, data volume, integrations, feature flags, timezones, and permission policies without copying uncontrolled sensitive data. Monitor whether a failure belongs to the product, test environment, third party, or test data, and keep blocked combinations visible until someone accepts or resolves the gap.
Manual testing is one part of a release system. QA automation provides fast repeatable feedback for stable rules and journeys; unit, component, integration, contract, and end-to-end checks should sit at the layer that gives the clearest signal. Manual exploration then focuses on change, ambiguity, interactions, and consequences that are difficult to encode in advance.
A product audit examines wider architecture, security, delivery, and ownership risk. Load testing measures behavior under realistic traffic and failure. Specialist security and accessibility assessment go beyond ordinary functional checks. Product deployment strengthens artifact traceability, rollout, monitoring, rollback, and recovery. These scopes complement manual QA and must be defined and evidenced separately.
Release quality also depends on observability and operations. Confirm that support can identify an affected user or transaction safely, important failures create useful telemetry, feature controls and rollback paths work, migrations are monitored, and incident ownership is clear. A successful pre-release test cannot prove that production dependencies, scale, or data will behave identically.
After release, compare evidence with reality: defects escaped, false alarms, support contacts, rollback or hotfixes, platform incidents, and coverage that produced little signal. Turn stable high-value checks into automation, remove obsolete cases, refine the risk model, and preserve exploratory charters that revealed important unknowns. QA improves when every release teaches the next one where confidence was justified and where it was borrowed.