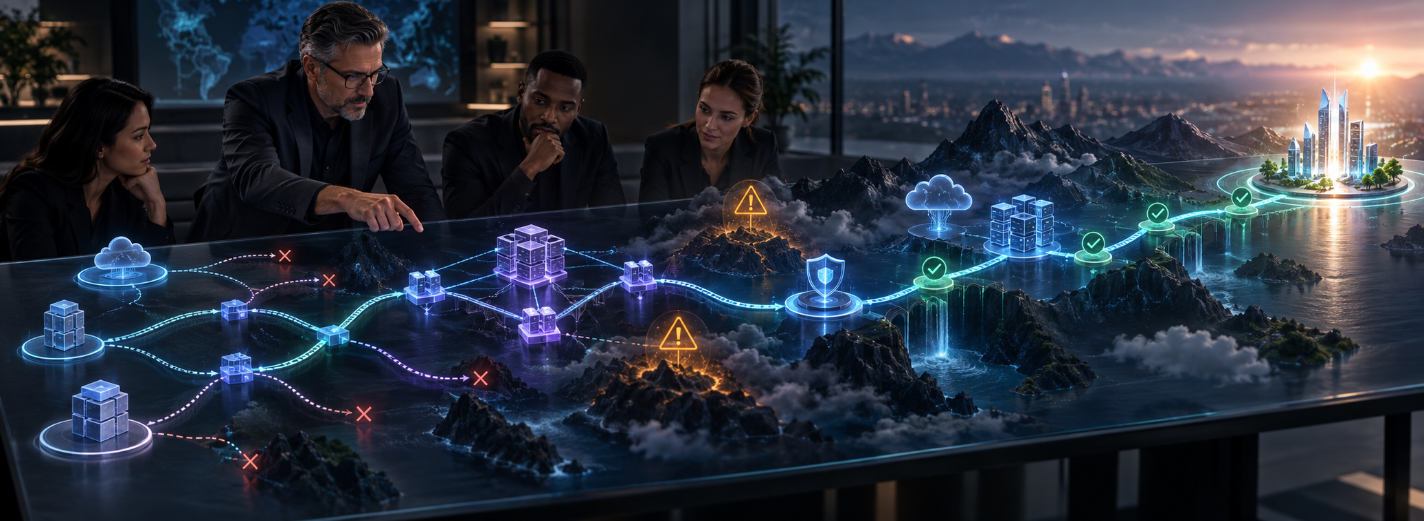
How to Create a Technical Roadmap That Guides Decisions
- roadmap
- fractional CTO
- technical leadership
How to Create a Technical Roadmap That Guides Decisions
Predictable software delivery does not mean every estimate becomes a promise and every promise lands on its original date. It means leaders can state what is likely, what remains uncertain, which assumptions control the range, how new information changes the forecast, and what decision follows. A predictable organization detects variance early enough to protect the business outcome rather than explaining it after the deadline.
The CTO’s role is to build that operating system across product, engineering, design, security, operations, and commercial commitments. The work combines smaller batches, visible flow, technical risk reduction, reliable release paths, explicit decision rights, and forecasts calibrated against actual history. Tools and metrics support the model; they cannot repair ambiguous priority or authority.
This guide is for founders and leaders whose roadmap conversations have become negotiations between optimism and distrust. For adjacent decisions, see scaling after the MVP, testing strategy, and creating a decision-oriented technical roadmap.
Define the Outcome and Mandate
Begin by defining the promise the organization needs to make. It may be confidence in a launch window, a steady stream of customer outcomes, a regulatory deadline, a migration before a vendor exit, or rapid recovery when a release fails. Name the users, business consequence, time horizon, acceptable range, and evidence required to update stakeholders. A single date without those boundaries invites false precision.
Separate outcomes from scope. If the outcome is “let enterprise administrators delegate access safely,” the team can discover a smaller path than a predetermined list of screens and integrations. Define what must be true, what is excluded, which quality and security constraints are fixed, and which features may move. This gives product and engineering legitimate options when evidence changes instead of forcing hidden compromise.
Give one owner authority to maintain the forecast and surface the decisions behind it. Product owns value and ordering, engineering owns technical evidence and feasible sequencing, and commercial leaders own the consequences of promises. The CTO makes conflicts visible and ensures a named person decides. A forecast assembled by consensus but owned by nobody will remain unchanged until reality disproves it.
Build an Evidence Baseline
Reconstruct how work actually moved through the system. Sample completed, abandoned, urgent, and delayed items across normal and difficult periods. Record arrival, commitment, start, review, test, release, and validation where the data exists. Add blocked time, dependency waiting, handoffs, rework, incidents, escaped defects, and unplanned demand. The purpose is to reveal queues and variation, not to grade individuals.
Use a balanced view of delivery. Flow measures such as throughput, cycle time distributions, work age, work in progress, and blocked time explain how commitments move. Delivery measures such as change lead time, deployment frequency, failed-deployment recovery time, change failure percentage, and deployment rework show throughput and instability at the production boundary. Product outcomes and reliability targets show whether shipping helped.
Segment the evidence before drawing conclusions. A tiny configuration change, a regulated payment flow, and a platform migration do not share one useful distribution. Separate classes of service, product areas, external dependencies, and planned from unplanned work. Use medians and percentiles rather than one average, preserve outliers for investigation, and document changes in measurement. Metrics become misleading when definitions move silently.
Make Decision Rights and Trade-offs Explicit
Reduce batch size before adding planning ceremony. Break initiatives into vertical slices that produce user or operational evidence across interface, behavior, data, integration, telemetry, and release. Smaller batches shorten feedback, expose integration assumptions, limit failure impact, and create more observations for forecasting. A list of technical layers may look organized while postponing the first proof of value.
Limit work in progress at the system constraint, not only within each discipline. Starting more work increases queues, context switching, aging, and the number of promises competing for scarce review, environments, product decisions, or specialist knowledge. Establish an expedite policy with a real cost: if urgent work enters, name what pauses and who accepts the consequence.
Map dependencies as decisions. For each external team, provider, approval, design, dataset, environment, or key person, name the needed result, request date, owner, service expectation, fallback, and latest safe decision point. Remove dependencies through clearer interfaces and ownership where practical. Where they remain, include their uncertainty in the forecast rather than treating waiting as an engineering delay.
Run the Roadmap as an Operating Cadence
Use a weekly flow review to make decisions about aging and blocked work. Inspect the oldest items and the constraint, compare new arrivals with completions, decide what to finish or stop, resolve priority conflicts, and assign dependency actions. Do not turn the meeting into a tour of every ticket. If no decision, changed priority, assigned action, or new evidence results, change or cancel the forum.
Run release readiness from explicit criteria: accepted product behavior, migration and compatibility, security and privacy controls, representative tests, performance evidence, telemetry, support preparation, deployment and rollback, and named authority. The criteria should scale with consequence rather than create one heavy gate for every change. Automation handles repeatable checks; people decide residual risk.
Calibrate forecasts monthly with product and business stakeholders. Compare predicted ranges with actual outcomes, identify which assumptions failed, and update the reference class or work breakdown. Forecast the remaining work from current flow and known dependencies, not from the percentage of tasks marked complete. Communicate a range and confidence, then state which decision would improve confidence most.
Plan Failure Scenarios and Controls
Technical controls make small promises safer. Maintain a reproducible build, fast feedback for common changes, protected mainline, deployable artifacts, reversible database evolution, feature controls where appropriate, representative automated checks, production telemetry, and a practiced rollback or repair path. Improve the slowest and least trustworthy part of the path before buying a larger toolchain.
Plan for interruption. Reserve capacity for incidents, support, security, maintenance, and discovery from observed demand rather than pretending every hour belongs to roadmap features. Define which events may interrupt committed work, who declares them, and how displaced work is re-forecast. Without this policy, urgent demand enters invisibly and the original plan remains politically unchanged.
Do not purchase predictability with overtime, padded estimates, reduced testing, or pressure to hide blocked work. These tactics can make one reporting period look stable while increasing defects, attrition, recovery time, and future uncertainty. Track team health, unplanned work, security findings, reliability, and customer impact as guardrails. A system is predictable only if it can repeat the result without exceptional effort.
Use Review and Exit Criteria
Measure forecast quality as a distribution. Track whether delivered outcomes fall within stated ranges, how early material variance becomes visible, how often scope changes after commitment, and how long decisions or dependencies remain unresolved. Pair forecast error with cycle time, throughput, instability, outcome, reliability, and team-health signals. One number can be improved by shifting harm elsewhere.
Review the operating model after enough cycles to see a pattern. Ask whether commitments are smaller, aging and blocked work are visible, priority changes have owners, releases are safer, and stakeholders receive earlier and more accurate information. Retain practices that change decisions; revise those that create noise; stop reports and meetings whose cost exceeds the evidence they produce.
For a portfolio, use scenarios rather than adding point estimates. Show the likely effect of keeping current work in progress, pausing one initiative, adding a dependency, protecting maintenance capacity, or moving a deadline. Historical throughput can inform probabilistic ranges when the work is comparable and the data is stable, but the model must disclose its reference class and exclusions. Simulation supports a decision; it does not turn novel work into certainty. Reforecast when the underlying system or demand materially changes.
The CTO succeeds when the organization can make and revise credible promises without relying on personal heroics. Product can trade scope openly, engineers can expose uncertainty without punishment, commercial leaders can distinguish aspiration from commitment, and executives can act before a forecast fails. Transfer metric definitions, decision rights, facilitation, and forecasting knowledge to the team. Predictability is a maintained capability, not a dashboard owned by one executive.
- Define the promise: state the outcome, forecast range, confidence, fixed constraints, flexible scope, owner, and evidence that will change the commitment.
- Measure the flow: use work age, cycle-time distributions, throughput, blocked and dependency time, unplanned demand, release performance, and product outcomes.
- Control the system: reduce batch size, limit work in progress, make expedite cost visible, remove dependencies, and protect a safe release path.
- Run decision cadences: review flow weekly, release against proportionate evidence, and calibrate forecasts with product and business stakeholders monthly.
- Protect honesty: expose uncertainty and blocked work; reject overtime, padding, quality cuts, and reporting conventions that manufacture apparent certainty.
- Learn and transfer: review forecast error, recovery, quality, security, outcomes, and team health; improve the constraint and distribute ownership of the model.
What should a CTO decide first when delivery is unpredictable?
What should a CTO decide first when delivery is unpredictable?
Which evidence is enough to begin improving delivery?
Which evidence is enough to begin improving delivery?
What is the most common mistake in delivery forecasting?
What is the most common mistake in delivery forecasting?
How often should a software delivery forecast be reviewed?
How often should a software delivery forecast be reviewed?
When is external technical leadership useful?
When is external technical leadership useful?
Turn Technical Priorities into a Decision System
Share the business outcomes, current architecture, delivery evidence, obligations, major risks, dependencies and planning horizon. We will define the smallest useful roadmap with accountable decisions, measurable milestones and a review cadence.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
How a CTO Makes Software Delivery Predictable
Build delivery confidence through explicit promises, visible flow, smaller batches, controlled dependencies, engineering evidence, calibrated forecasts, and clear decision rights.
8 min read
08 Sep 2026
The First 30 Days with a Fractional CTO: From Evidence to Operating Priorities
Structure the first month around a clear mandate, trustworthy evidence, urgent containment, decision rights, operating cadence, a focused 90-day plan, and capability transfer.
8 min read
08 Sep 2026
How to Scope an Angular Migration Without Hiding the Risk
A practical guide to Angular migration assessment, version and build updates, optional modernization, migration boundaries, regression evidence, responsibilities, engagement models, risk pricing, and knowledge transfer.
9 min read
08 Sep 2026