Azure Functions vs Container Apps: A Production Decision Guide
- Azure Functions vs Container Apps
- azure
- architecture
- development
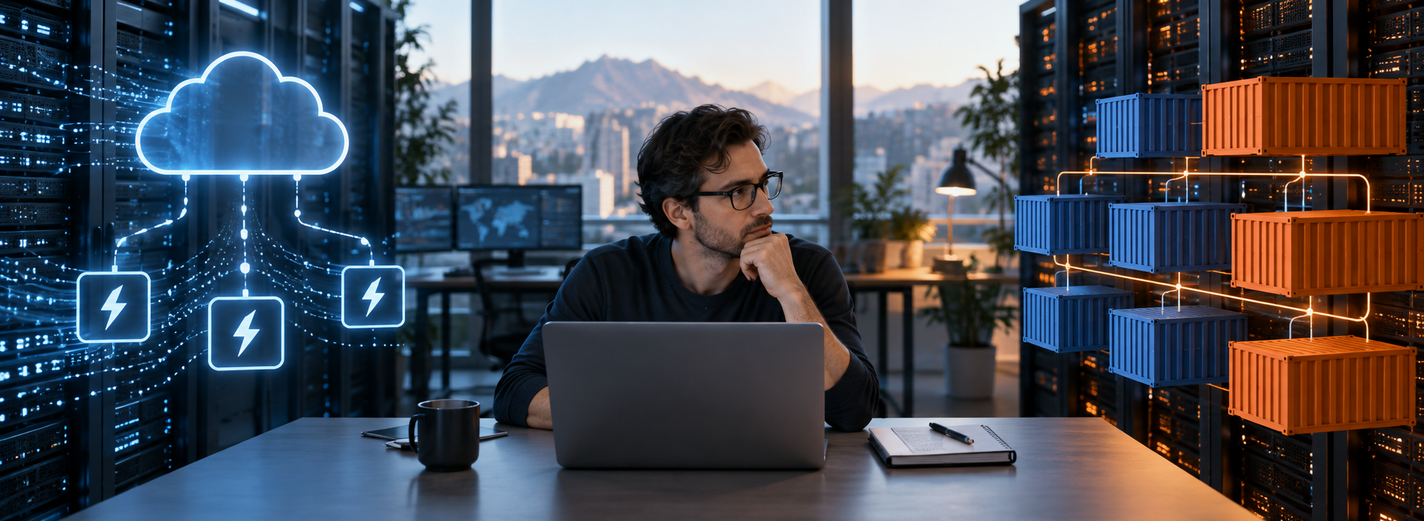
Azure Functions and Azure Container Apps overlap, but they optimize different decisions. Functions begins with an event-driven programming model: a trigger invokes focused code, bindings can connect supported services, and the platform manages the host. Container Apps begins with a Linux container: the team controls the process, image, ports, protocols, dependencies, health probes, and runtime shape while Azure manages the underlying Kubernetes-based environment.
The boundary is deliberately porous. A function app packaged as a Linux container can run on Azure Container Apps, combining Functions triggers and bindings with Container Apps networking, revisions, workload profiles, KEDA-based scaling, Dapr, and a shared environment for APIs, workers, and other services. The useful comparison is therefore not “serverless or containers.” It is how much programming convention, runtime control, platform responsibility, and operational consistency the workload needs.
Write down the critical journey before selecting a host: event source, response deadline, execution duration, concurrency, burst shape, state, dependencies, network path, recovery promise, deployment frequency, security obligations, and owner. Then choose the smallest operating model that meets those conditions. A familiar service name is not evidence; a representative vertical slice under realistic load and failure is.
Start with the Programming and Operating Model
Choose native Azure Functions hosting when the function programming model matches the work and the team wants Azure to own more of the execution host. Triggers, bindings, managed scaling, deployment tooling, and Application Insights integration reduce the machinery around focused event handlers. Flex Consumption is the current general serverless starting point for new Linux function apps when its regional and feature support fits: it combines execution-based billing, virtual network integration, configurable instance memory, per-function scaling for many trigger types, and optional always-ready instances.
Choose Container Apps when the deployable unit is naturally a containerized API, worker, web application, protocol endpoint, or mixed service; when image control and arbitrary dependencies matter; or when several workloads should share one environment, networking model, revision workflow, and operating practice. You own the image and must patch and rebuild it. Container Apps exposes more knobs, which creates useful control and corresponding responsibility.
Functions on Container Apps is a third answer, not a compromise to hide. It is useful when developers benefit from the Functions model while the platform needs Container Apps features or colocation with other containerized workloads. Validate trigger-specific scaling and authentication support, because not every binding has identical dynamic-scaling behavior in that host. Make the resource provider and hosting model explicit in architecture and runbooks; superficially similar deployments can have different lifecycle and support implications.
Scaling and Cold Starts Are Workload Properties
Scale-to-zero trades idle cost for startup latency. The real question is whether the first event after idle can tolerate image retrieval, host initialization, dependency loading, connection establishment, and application warm-up. Measure the entire journey at p95 and p99, including downstream calls. For synchronous user traffic, keep capacity ready when the latency budget requires it. Flex Consumption offers always-ready instances by scale group; Functions Premium uses prewarmed capacity; Container Apps avoids cold start when minimum replicas are greater than zero.
Scaling also depends on concurrency and the event source. A high replica limit cannot compensate for a slow scale curve, a database connection ceiling, a downstream quota, or one message that monopolizes CPU. Configure per-instance concurrency from evidence, cap maximum replicas to protect dependencies, and apply backpressure. Test from zero, normal steady state, sudden burst, sustained peak, scale-in, and dependency degradation. Observe event age, rejected work, retries, saturation, and useful throughput rather than instance count alone.
Design Long-Running Work Around Checkpoints
A generous execution timeout does not make a long task reliable. Long work must survive process replacement, deployment, retry, and partial completion. Divide it into idempotent steps with durable checkpoints, bounded attempts, explicit compensation, progress visibility, and a dead-letter or operator path. Durable Functions is valuable when its orchestration model fits; Container Apps Jobs suit finite container executions, schedules, and event-triggered jobs; a continuously running Container App suits workers that own a process or protocol.
Choose by lifecycle, not duration alone. Ask who starts the work, how parallelism is limited, where state lives, how cancellation works, what happens after a duplicate, how a new version handles in-flight state, and how support resumes or abandons an item. Keep large payloads in durable storage and pass references. Test termination between checkpoints, poison input, dependency recovery, replay, deployment during execution, and backlog drainage. The successful outcome is a recoverable workflow, not a process that happened to run for hours once.
Let Event Semantics Drive the Runtime
Functions offers a productive catalog of triggers and bindings, while Container Apps can scale containers from HTTP traffic or KEDA-supported event sources and can host Functions containers. Do not select by connector count. Define delivery semantics: acknowledgement point, retry policy, visibility or lock duration, ordering scope, duplicate behavior, poison-message handling, replay, retention, partitioning, and the maximum acceptable event age.
Assume at-least-once delivery unless a documented end-to-end guarantee proves otherwise. Make consumers idempotent with a business key or processed-message record, and make side effects safe to repeat. Couple state changes and event publication with an outbox or another proven consistency pattern where loss matters. Bound retries with delay and jitter; infinite immediate retries convert one bad dependency into an outage. Scale rules should reflect useful work and protect downstream capacity, not simply chase queue length.
Instrument the event journey from producer to business outcome. Correlation, enqueue time, dequeue count, processing version, result, and dead-letter reason should be searchable without reading raw payloads containing sensitive data. Test duplicates, out-of-order delivery, partition hotspots, expired locks, unavailable dependencies, poison input, scale-out, scale-in, and replay of historical volume. Runtime choice follows the semantics and ownership this evidence reveals.
Treat Networking as Architecture, Not a Checkbox
Map every inbound and outbound path before comparing networking features. Identify public entry points, private dependencies, DNS zones, egress destinations, ports, certificates, identities, inspection requirements, and failure owners. Flex Consumption supports virtual network integration; Container Apps environments can expose internal or external ingress and provide a shared network boundary for multiple apps. Exact capabilities still depend on the plan, environment type, region, and architecture, so validate the intended topology rather than assuming feature parity.
Prefer managed identity and Microsoft Entra authorization over stored credentials where the target service supports them. Restrict ingress and egress to the required paths, plan DNS and private endpoints together, and make certificate ownership and rotation explicit. Account for NAT and connection limits, ephemeral ports, firewall rules, proxy behavior, and downstream quotas under scale-out. A thousand new replicas that each open fresh connections can overwhelm a healthy database or appliance.
Test name resolution, identity token acquisition, certificate renewal, dependency timeout, connection reuse, regional failover, and diagnostic access from the real network path. Keep emergency access narrow, time-bound, and audited. Network isolation that prevents operators from observing or recovering the service is incomplete architecture.
Compare Delivery and Observability End to End
Native Functions deployment can be code-centered; Container Apps deployment is image-centered. Image ownership adds a Dockerfile, registry, base-image and operating-system updates, vulnerability scanning, provenance, and rebuilds even when application code is unchanged. In return it creates a portable, immutable unit with explicit system dependencies. Functions containers on Container Apps retain that image lifecycle while also requiring Functions runtime compatibility.
Build once from reviewed source and promote the same artifact. Provision host, identities, networking, scale rules, secrets references, diagnostics, and alerts as code. Use deployment slots or revision traffic splitting where the chosen host and plan support the required behavior, but verify how triggers and background consumers behave: sending ten percent of HTTP traffic to a new revision does not automatically canary queue consumption. Protect schema and event compatibility across coexisting versions and define rollback and roll-forward paths.
Connect telemetry across the business journey. Application Insights can monitor Functions, while Container Apps integrates with Azure Monitor and Log Analytics; OpenTelemetry can carry trace context across both. Standardize service, version, environment, operation, tenant-safe correlation, and dependency fields. Track latency, errors, saturation, event age, retry and dead-letter rates, replica decisions, cold starts, deployment health, and cost. Logs without retention, queries, alert ownership, and runbooks are stored uncertainty.
Exercise the operating model: deploy during load, roll back, rotate a secret, rebuild a base image, restore data, investigate one failed event, and hand the incident to the named responder. The better runtime is the one the actual team can release, understand, patch, and recover consistently.
Build a Cost Model from Real Demand
Do not compare a single Functions execution price with a single Container Apps compute price. Model a month of demand: executions, duration, memory, CPU, concurrency, idle periods, minimum warm capacity, replicas, jobs, traffic distribution, and growth. Add storage transactions, queues, registries, image transfer, Log Analytics ingestion and retention, Application Insights, egress, private networking components, certificates, backups, and support. Pricing meters and included grants change, so use current regional calculators and validate the bill after a representative pilot.
Functions consumption economics are attractive for intermittent, short, event-driven work, but always-ready capacity, heavy memory, long executions, or inefficient concurrency can change the curve. Container Apps consumption can also scale to zero and charge for active resources, while dedicated workload profiles trade utilization risk for predictable reserved capacity and specialized compute. Consolidating workloads may improve utilization yet increase blast radius and coordination. Separate environments can improve isolation while duplicating fixed costs.
Include engineering and risk. Estimate image maintenance, platform code, network and identity design, diagnostics, release machinery, on-call load, incident recovery, security patching, and time lost to a model that does not fit the application. Compare cost per successful business outcome at normal load, burst, idle, and failure—not cost per abstract invocation. Set budget alerts and unit-cost dashboards, then revisit the model when traffic shape, latency targets, dependencies, or team capability changes.
Use External Expertise to Retire Uncertainty
External review is useful when the decision crosses application code, event semantics, identity, private networking, data, infrastructure, security, and finance; when production symptoms contradict the current design; or when the team has not operated the candidate model at comparable scale. The review should reduce uncertainty, not outsource ownership.
A credible assessment delivers a workload map, baselines, tested options, architecture decisions, cost ranges with assumptions, priority risks, a thin production-shaped experiment, acceptance thresholds, migration and coexistence steps, rollback, operational ownership, and knowledge transfer. GARNO.TECH can turn that assessment into owned work packages through our Microsoft Azure development services. The recommendation may be Functions, Container Apps, Functions on Container Apps, or a deliberate combination; the evidence should decide.
- Programming model: choose focused triggers and bindings, an arbitrary container process, or Functions in a container from the code lifecycle and control the team actually needs.
- Latency and scale: test from zero through burst and sustained peak; set warm capacity, concurrency, replica bounds, and backpressure from user deadlines and dependency limits.
- Execution lifecycle: design long work for checkpoints, retries, cancellation, version coexistence, recovery, and operator intervention rather than relying on a timeout.
- Event correctness: define acknowledgement, idempotency, ordering, retry, poison handling, replay, retention, and event-age objectives before selecting a trigger or scaler.
- Security and network: map every path, identity, DNS dependency, certificate, egress destination, quota, and recovery route under the intended environment and plan.
- Ownership and economics: include artifacts, patching, telemetry, release, incidents, support, fixed capacity, dependent services, and engineering time in cost per successful outcome.
Are Azure Functions and Azure Container Apps mutually exclusive?
Are Azure Functions and Azure Container Apps mutually exclusive?
Which option is better for low cold-start latency?
Which option is better for low cold-start latency?
Should long-running work use Container Apps instead of Functions?
Should long-running work use Container Apps instead of Functions?
Which service is better for event processing?
Which service is better for event processing?
How should a team compare cost?
How should a team compare cost?
Choose the Azure Runtime from Workload Evidence
Share the event sources, critical journeys, latency and recovery targets, duration, traffic profile, dependencies, network boundaries, current bill, delivery flow, and ownership. GARNO.TECH will compare native Functions, Container Apps, and Functions on Container Apps and define a testable recommendation, migration sequence, acceptance thresholds, rollback, and knowledge transfer.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
Angular Real-Time Architecture with WebSocket, SSE, and RxJS
Choose polling, SSE, or WebSocket from product semantics, then design typed RxJS streams, reconnection, authentication, gap recovery, state reconciliation, memory safety, and production observability.
10 min read
18 Sep 2026
NestJS Architecture for SaaS and Business Platforms
Design a NestJS platform around domain ownership, tenant isolation, authorization, subscription state, reliable integrations and jobs, data growth, observability, delivery, and an affordable path to scale.
9 min read
05 Aug 2026
Angular Design Systems: Build a Product, Not a Component Catalogue
A production guide to Angular design-system architecture and governance: ownership, semantic tokens, primitives, accessibility contracts, stable APIs, versioning, documentation, contributions, adoption, exceptions, and measurable outcomes.
10 min read
08 Sep 2026