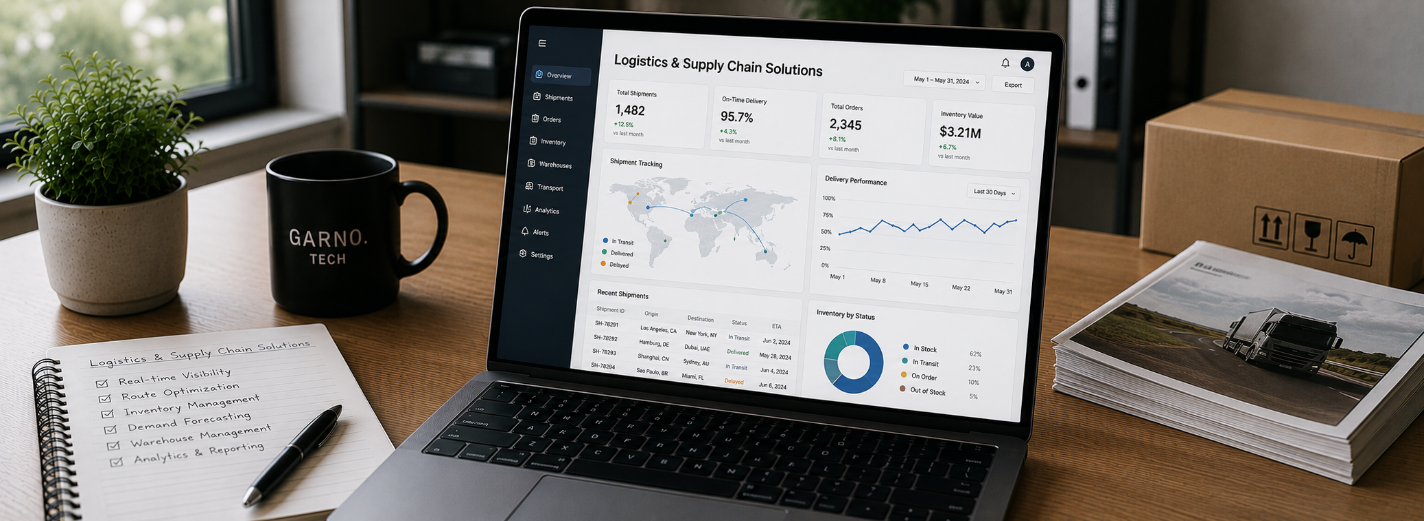
Main Our Solutions
Logistics and Supply Chain Software: From Fragmented Events to Operational Control
Logistics and Supply Chain Software: From Fragmented Events to Operational Control
- logistics software solutions
- supply chain software
- transportation management system
- warehouse management system
- route optimization
- inventory tracking
- order fulfillment
- logistics automation
- shipping integrations
Logistics software lives where commercial promises meet physical reality. A customer expects a delivery on Tuesday; the warehouse has partial stock in two locations; a carrier changes capacity; customs requests another document; a damaged pallet arrives late. The platform must preserve a trustworthy account of what was promised, what physically happened, what is expected next, and who can change the plan.
This is why a logistics transformation cannot be reduced to buying a TMS, WMS, or route optimizer. Those products may be essential, but value appears only when order management, inventory, warehousing, transport, finance, customer communication, and partner operations share consistent identifiers, states, and events. Otherwise, each new system becomes another screen that employees reconcile in spreadsheets and phone calls.
Good logistics and supply chain software creates operational control under imperfect conditions. It distinguishes planned from actual movement, inventory on hand from inventory available to promise, a late status message from a late shipment, and an exception that needs a person from noise that can be handled automatically. It supports ordinary work quickly and makes unusual work visible with enough context to decide.
GARNO.TECH designs and develops connected platforms for manufacturers, distributors, retailers, carriers, fulfillment operators, and logistics technology companies. The work can begin with one costly constraint—manual dispatching, unreliable inventory, fragmented carrier integration—or with a new product. The durable objective is the same: establish a reliable flow of decisions and evidence from order commitment to final delivery.
Start With the Operating Model, Not the Feature List
Before defining screens, map the decisions and state transitions in the operation. How does an order become a reservation, pick task, package, consignment, route stop, proof of delivery, invoice, return, or claim? Which transitions are automatic, which require approval, and which can be reversed? What evidence must exist before the next party accepts responsibility? These questions expose the real scope far better than a generic module checklist.
A transportation capability may cover rate and carrier selection, consolidation, load building, tendering, dispatch, appointment windows, tracking, proof of delivery, freight audit, and claims. A warehouse capability may cover receiving, quality inspection, directed putaway, replenishment, wave or zone picking, packing, cycle counting, yard movements, returns, and labor planning. Order orchestration connects sales channels to available-to-promise stock, fulfillment rules, split shipments, substitutions, backorders, and customer communication.
The workflows depend on the operating model. A parcel network, cold chain, bulk carrier, spare-parts distributor, marketplace, and 3PL may all use the word “shipment,” yet require different custody, temperature, documentation, liability, and billing rules. Model those rules explicitly. Avoid encoding them as scattered conditions in user interfaces or integration scripts, where nobody can see the complete policy.
Design for exceptions at the same time as the happy path. A late vehicle, short pick, damaged item, rejected tender, missing customs code, duplicate scan, or customer address correction needs a state, severity, owner, deadline, allowed actions, and audit trail. The interface should present the next safe decision and its consequences. Automation should complete deterministic work; people should handle ambiguity, negotiation, and high-impact tradeoffs.
Access follows responsibility. A supplier, carrier, warehouse employee, customer-service agent, finance analyst, and client administrator should see the smallest useful view and act only within a defined scope. Sensitive rates, personal data, location history, and trade documents need retention, export, and audit rules from the beginning—not after a partner portal is already live.
Build a Shared Language for Orders, Stock, and Movement
A connected supply chain needs shared meaning before it needs more APIs. Define stable identities for products, locations, parties, handling units, orders, consignments, vehicles, and documents. Decide which system is authoritative for each entity and which copies are projections for local work. Standards can reduce translation: the UN/CEFACT supply-chain models provide common semantics for trade and transport exchange, while GS1 EPCIS expresses visibility events around what happened, when, where, and why.
The operational model should separate intent, execution, and observation. An order or transport plan states what should happen. Tasks and assignments describe authorized work. Events record what participants or devices report. A derived current state summarizes those events for fast decisions. Keeping these concepts distinct prevents a late scan from silently rewriting history or an optimistic plan from being mistaken for physical inventory.
Integrations must assume messages can be late, duplicated, missing, reordered, or corrected. Give every command and event a stable identifier. Make consumers idempotent, preserve source timestamps and receipt timestamps, validate schemas, quarantine invalid payloads, and expose replay and reconciliation tools. Retries need backoff and a terminal path; a queue that retries forever merely hides a permanent failure. For critical exchanges, compare aggregates—orders, quantities, money, and status counts—rather than waiting for a partner to notice drift.
Reconciliation deserves its own product workflow. Show unmatched records, quantity or value differences, the last successful checkpoint, probable cause, and permitted corrective actions. Preserve the original evidence when an operator resolves a discrepancy; do not overwrite history with the corrected state. This matters because logistics data eventually reaches invoices, customer claims, inventory valuation, regulatory documents, and partner performance reports. A repair that makes one dashboard green can create a financial inconsistency elsewhere.
Choose synchronous calls only when the caller truly needs an immediate answer. Publish events for state changes that several consumers may use, and use asynchronous commands for work that can be accepted and completed later. Protect boundaries with adapters so a carrier-specific code or an ERP field does not become the company’s domain language. Version contracts compatibly and test them with real examples from both sides.
Architecture should follow ownership and failure isolation. A modular monolith may be the safest starting point for one team; independently deployable services make sense when domains have distinct scale, release cadence, data ownership, or availability needs. In either case, trace a business transaction across modules and partners, encrypt sensitive data, apply least-privilege access, test recovery, and keep a complete audit trail of automated and manual decisions.
Turn Visibility Into Decisions and Controlled Automation
Real-time visibility does not mean painting every incoming event on a map. It means presenting the freshest trustworthy state, its source and age, the uncertainty around it, and the action that follows. A vehicle ping from two minutes ago, a carrier estimate calculated yesterday, and a warehouse scan confirmed by an employee are different qualities of evidence. Show that difference instead of manufacturing false precision.
Design dashboards around operating decisions. A dispatcher needs unassigned work, capacity conflicts, route risk, and actions before a cutoff. A warehouse supervisor needs backlog by zone, blocked tasks, replenishment risk, labor balance, and equipment health. Customer service needs the promise, latest credible status, reason for deviation, and available remedy. Executives need trends and economic outcomes, not a wall of live dots.
Exception management converts visibility into control. Detect the condition, estimate impact, group related symptoms, assign ownership, set a response deadline, recommend permitted actions, and track resolution. Use rules for known thresholds and statistical or machine-learning methods where patterns justify them, but preserve an explanation and a safe manual override. An alert without an owner or action is operational noise.
Route and load optimization must solve the executable problem rather than the mathematically neat one. Include delivery windows, driver hours, skills, vehicle and compartment capacity, loading sequence, depot rules, traffic, service priorities, legal restrictions, and the cost of changing an accepted plan. Re-optimize selectively when reality changes; constant global replanning can destabilize dispatch and confuse drivers.
Measure the system through business flow: perfect-order rate, on-time-in-full delivery, inventory accuracy, dock-to-stock time, pick productivity and error rate, order cycle time, empty distance, vehicle utilization, cost per shipment or unit, claims, returns, exception age, and time to recover from integration failure. Segment by location, partner, customer, route, product class, and reason code. A metric becomes useful when someone owns the decision it informs and can trace it back to reliable events.
Supply-chain visibility is useful only when the platform can explain the evidence behind a state, identify who owns the exception, and present the next safe action before the promise is broken. A useful control tower reduces uncertainty; it does not simply redraw that uncertainty on a larger screen for more people.
— GARNO.TECH
Modernize the Constraint Without Stopping the Operation
The safest logistics modernization starts with a bounded operational problem and a measurable outcome. Map the current flow with the people who dispatch, receive, pick, reconcile, support customers, and close the books. Quantify manual touches, waiting, error correction, missed service levels, claims, and work hidden outside the system. Then select a slice with meaningful value and manageable dependencies—for example, carrier status normalization for one region or exception handling for one fulfillment flow.
Define the target states, ownership, data contract, controls, and success measures before choosing the interface or technology. Build an adapter around the legacy system rather than coupling new logic to its tables. Run the new flow in shadow mode, reconcile results, and let operators compare recommendations with actual outcomes. Introduce automation progressively: suggest, require approval, then automate low-risk cases after evidence earns trust.
Migration must preserve daily operations. Plan cutover by partner, facility, route, customer, or order cohort; keep idempotent replay and rollback paths; and verify inventory, open orders, documents, money, and responsibility at each boundary. Train by role with realistic exceptions, not only the happy path. During stabilization, put business and technical owners in the same response loop and make unresolved discrepancies visible.
Test the operational envelope, not only functional correctness. Rehearse peak order intake, scanner outages, delayed carrier responses, queue backlog, partial warehouse connectivity, and recovery from the last trusted checkpoint. Define how long each workflow may be unavailable, how much data may be re-entered, and which degraded manual procedure keeps goods moving safely. Capacity and recovery results should become explicit launch criteria.
Plan ownership after launch. Name the team responsible for each integration, business rule, alert, reference-data set, and reconciliation queue. Establish service levels with partners, review exception trends, rotate credentials, restore backups, and practice incident response. A system is not maintainable merely because its code is clean; it is maintainable when operators can explain its state and recover it under pressure.
GARNO.TECH can lead discovery, product and UX design, architecture, implementation, integrations, data migration, QA, infrastructure, and rollout—or strengthen a specific stage with your team. Bring one representative order journey, the systems and partners it touches, current failure evidence, and the metric you need to improve. We will turn that material into an incremental delivery plan whose value can be verified in operation.
Publications
Our research
Research and development of AI-powered solutions to optimize business workflows and enhance decision-making processes.
Analysis of machine learning models for predictive analytics in finance, e-commerce, and SaaS platforms.
Exploration of natural language processing and computer vision technologies to strengthen automation, personalization, and customer support.
FinTech Solutions: Architecture for Payments, Wallets, and Financial Operations
Explore how reliable FinTech solutions combine customer journeys, payment orchestration, wallets, ledgers, KYC and AML workflows, provider integrations, reconciliation, security, and operations.
8 min read
24 Jul 2026
Real Estate Software That Reflects How Property Operations Actually Work
Design PropTech around property data, listing rights, search, leads, leases, tenants, maintenance, payments, integrations, analytics, privacy, and operational exceptions.
8 min read
24 Jul 2026
Custom Digital Platforms: From Fragmented Work to an Operable System
A practical guide to deciding when a custom platform is justified and designing portals, workflows, integrations, data ownership, automation, analytics, security, and staged delivery.
8 min read
24 Jul 2026